Skip to content
Toggle navigation
P
Projects
G
Groups
S
Snippets
Help
赵月辉
/
fastgpt-migrated
This project
Loading...
Sign in
Toggle navigation
Go to a project
Project
Repository
Issues
0
Merge Requests
0
Pipelines
Wiki
Snippets
Members
Activity
Graph
Charts
Create a new issue
Jobs
Commits
Issue Boards
Files
Commits
Branches
Tags
Contributors
Graph
Compare
Charts
Unverified
Commit
aab6ee51
authored
Jan 22, 2024
by
Archer
Committed by
GitHub
Jan 22, 2024
Browse files
Options
Browse Files
Download
Email Patches
Plain Diff
V4.6.7-production (#759)
parent
91b7d81c
Hide whitespace changes
Inline
Side-by-side
Showing
41 changed files
with
1622 additions
and
1958 deletions
+1622
-1958
README.md
+6
-6
README_en.md
+46
-42
docSite/content/docs/development/openapi/chat.md
+2
-2
docSite/content/docs/development/openapi/dataset.md
+844
-1022
docSite/content/docs/development/upgrading/467.md
+5
-4
packages/global/common/error/utils.ts
+3
-1
packages/global/common/string/tools.ts
+6
-0
packages/service/common/file/utils.ts
+1
-1
packages/service/common/response/index.ts
+3
-2
packages/service/support/permission/controller.ts
+4
-0
packages/web/components/common/Icon/icons/support/account/loginoutLight.svg
+13
-2
projects/app/public/docs/versionIntro.md
+6
-5
projects/app/public/locales/zh/common.json
+3
-2
projects/app/src/components/ChatBox/MessageInput.tsx
+20
-6
projects/app/src/components/ChatBox/index.tsx
+413
-355
projects/app/src/components/Markdown/index.tsx
+69
-60
projects/app/src/components/common/Textarea/TagTextarea.tsx
+2
-0
projects/app/src/components/core/module/AIChatSettingsModal.tsx
+9
-4
projects/app/src/components/support/user/team/TeamManageModal/InviteModal.tsx
+7
-5
projects/app/src/components/support/user/team/TeamManageModal/index.tsx
+2
-8
projects/app/src/pages/account/components/Info.tsx
+24
-20
projects/app/src/pages/api/core/dataset/collection/create/file.ts
+0
-85
projects/app/src/pages/api/core/dataset/collection/create/link.ts
+0
-91
projects/app/src/pages/api/core/dataset/collection/create/text.ts
+0
-117
projects/app/src/pages/api/core/dataset/create.ts
+5
-4
projects/app/src/pages/api/core/dataset/delete.ts
+7
-1
projects/app/src/pages/api/plusApi/[...path].ts
+0
-64
projects/app/src/pages/api/proApi/[...path].ts
+56
-0
projects/app/src/pages/dataset/detail/index.tsx
+1
-1
projects/app/src/pages/dataset/list/index.tsx
+17
-4
projects/app/src/pages/login/provider.tsx
+3
-3
projects/app/src/web/common/hooks/useConfirm.tsx
+3
-3
projects/app/src/web/core/dataset/api.ts
+2
-2
projects/app/src/web/core/dataset/utils.ts
+14
-10
projects/app/src/web/support/activity/promotion/api.ts
+2
-2
projects/app/src/web/support/user/api.ts
+5
-5
projects/app/src/web/support/user/inform/api.ts
+3
-3
projects/app/src/web/support/user/team/api.ts
+11
-11
projects/app/src/web/support/wallet/bill/api.ts
+1
-1
projects/app/src/web/support/wallet/pay/api.ts
+3
-3
projects/app/src/web/support/wallet/sub/api.ts
+1
-1
No files found.
README.md
View file @
aab6ee51
...
...
@@ -57,7 +57,7 @@ https://github.com/labring/FastGPT/assets/15308462/7d3a38df-eb0e-4388-9250-2409b
-
[
x
]
源文件引用追踪
-
[
x
]
模块封装,实现多级复用
-
[
x
]
混合检索 & 重排
-
[
]
自查询规划
-
[
]
Tool 模块
-
[
]
嵌入
[
Laf
](
https://github.com/labring/laf
)
,实现在线编写 HTTP 模块
-
[
]
插件封装功能
...
...
@@ -67,10 +67,10 @@ https://github.com/labring/FastGPT/assets/15308462/7d3a38df-eb0e-4388-9250-2409b
-
[
x
]
支持知识库单独设置向量模型
-
[
x
]
源文件存储
-
[
x
]
支持手动输入,直接分段,QA 拆分导入
-
[
x
]
支持 pdf、word、txt、md 等常用文件,支持 url 读取、CSV 批量导入
-
[
]
支持 HTML、csv、PPT、Excel 导入
-
[
x
]
支持 pdf,docx,txt,html,md,csv
-
[
x
]
支持 url 读取、CSV 批量导入
-
[
]
支持 PPT、Excel 导入
-
[
]
支持文件阅读器
-
[
]
支持差异性文件同步
-
[
]
更多的数据预处理方案
`3`
应用调试能力
...
...
@@ -81,8 +81,8 @@ https://github.com/labring/FastGPT/assets/15308462/7d3a38df-eb0e-4388-9250-2409b
-
[
]
高级编排 DeBug 模式
`4`
OpenAPI 接口
-
[
x
]
completions 接口 (对齐 GPT 接口)
-
[
]
知识库 CRUD
-
[
x
]
completions 接口 (
chat 模式
对齐 GPT 接口)
-
[
x
]
知识库 CRUD
-
[
]
对话 CRUD
`5`
运营能力
...
...
README_en.md
View file @
aab6ee51
...
...
@@ -49,48 +49,52 @@ Cloud: [fastgpt.in](https://fastgpt.in/)
## 💡 Features
1.
Powerful visual workflows: Effortlessly craft AI applications
-
[
x
]
Simple mode on deck - no need for manual arrangement
-
[
x
]
User dialogue pre-guidance
-
[
x
]
Global variables
-
[
x
]
Knowledge base search
-
[
x
]
Dialogue via multiple LLM models
-
[
x
]
Text magic - convert to structured data
-
[
x
]
Extend with HTTP
-
[
]
Embed Laf for on-the-fly HTTP module crafting
-
[
x
]
Directions for the next dialogue steps
-
[
x
]
Tracking source file references
-
[
]
Custom file reader
-
[
]
Modules are packaged into plug-ins to achieve reuse
2.
Extensive knowledge base preprocessing
-
[
x
]
Reuse and mix multiple knowledge bases
-
[
x
]
Track chunk modifications and deletions
-
[
x
]
Supports manual entries, direct segmentation, and QA split imports
-
[
x
]
Supports URL fetching and batch CSV imports
-
[
x
]
Supports Set unique vector models for knowledge bases
-
[
x
]
Store original files
-
[
]
File learning Agent
3.
Multiple effect testing channels
-
[
x
]
Single-point knowledge base search test
-
[
x
]
Feedback references and ability to modify and delete during dialogue
-
[
x
]
Complete context presentation
-
[
]
Complete module intermediate value presentation
4.
OpenAPI
-
[
x
]
completions interface (aligned with GPT interface)
-
[
]
Knowledge base CRUD
5.
Operational functions
-
[
x
]
Login-free sharing window
-
[
x
]
One-click embedding with Iframe
-
[
]
Unified access to dialogue records
`1`
Application Orchestration Features
-
[
x
]
Offers a straightforward mode, eliminating the need for complex orchestration
-
[
x
]
Provides clear next-step instructions in dialogues
-
[
x
]
Facilitates workflow orchestration
-
[
x
]
Tracks references in source files
-
[
x
]
Encapsulates modules for enhanced reuse at multiple levels
-
[
x
]
Combines search and reordering functions
-
[
]
Includes a tool module
-
[
]
Integrates
[
Laf
](
https://github.com/labring/laf
)
for online HTTP module creation
-
[
]
Plugin encapsulation capabilities
`2`
Knowledge Base Features
-
[
x
]
Allows for the mixed use of multiple databases
-
[
x
]
Keeps track of modifications and deletions in data chunks
-
[
x
]
Enables specific vector models for each knowledge base
-
[
x
]
Stores original source files
-
[
x
]
Supports direct input and segment-based QA import
-
[
x
]
Compatible with a variety of file formats: pdf, docx, txt, html, md, csv
-
[
x
]
Facilitates URL reading and bulk CSV importing
-
[
]
Supports PPT and Excel file import
-
[
]
Features a file reader
-
[
]
Offers diverse data preprocessing options
`3`
Application Debugging Features
-
[
x
]
Enables targeted search testing within the knowledge base
-
[
x
]
Allows feedback, editing, and deletion during conversations
-
[
x
]
Presents the full context of interactions
-
[
x
]
Displays all intermediate values within modules
-
[
]
Advanced DeBug mode for orchestration
`4`
OpenAPI Interface
-
[
x
]
The completions interface (aligned with GPT's chat mode interface)
-
[
x
]
CRUD operations for the knowledge base
-
[
]
CRUD operations for conversations
`5`
Operational Features
-
[
x
]
Share without requiring login
-
[
x
]
Easy embedding with Iframe
-
[
x
]
Customizable chat window embedding with features like default open, drag-and-drop
-
[
x
]
Centralizes conversation records for review and annotation
<a
href=
"#readme"
>
<img
src=
"https://img.shields.io/badge/-Back_to_Top-7d09f1.svg"
alt=
"#"
align=
"right"
>
...
...
docSite/content/docs/development/openapi/chat.md
View file @
aab6ee51
...
...
@@ -48,7 +48,7 @@ curl --location --request POST 'https://api.fastgpt.in/api/v1/chat/completions'
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"
detail=true 响应
"
>
}}
{{
<
tab
tabName=
"
参数说明
"
>
}}
{{
<
markdownify
>
}}
{{% alert context="info" %}}
...
...
@@ -56,7 +56,7 @@ curl --location --request POST 'https://api.fastgpt.in/api/v1/chat/completions'
-
chatId: string | undefined 。
-
为
`undefined`
时(不传入),不使用 FastGpt 提供的上下文功能,完全通过传入的 messages 构建上下文。 不会将你的记录存储到数据库中,你也无法在记录汇总中查阅到。
-
为
`非空字符串`
时,意味着使用 chatId 进行对话,自动从 FastGpt 数据库取历史记录,并使用 messages 数组最后一个内容作为用户问题。请自行确保 chatId 唯一,长度小于250,通常可以是自己系统的对话框ID。
-
messages: 结构与
[
GPT接口
](
https://platform.openai.com/docs/api-reference/chat/object
)
完全
一致。
-
messages: 结构与
[
GPT接口
](
https://platform.openai.com/docs/api-reference/chat/object
)
chat模式
一致。
-
detail: 是否返回中间值(模块状态,响应的完整结果等),
`stream模式`
下会通过
`event`
进行区分,
`非stream模式`
结果保存在
`responseData`
中。
-
variables: 模块变量,一个对象,会替换模块中,输入框内容里的
`{{key}}`
{{% /alert %}}
...
...
docSite/content/docs/development/openapi/dataset.md
View file @
aab6ee51
...
...
@@ -15,7 +15,9 @@ weight: 853
## 创建训练订单
**请求示例**
{{
<
tabs
tabTotal=
"2"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
POST
'https://api.fastgpt.in/api/support/wallet/bill/createTrainingBill'
\
...
...
@@ -26,7 +28,11 @@ curl --location --request POST 'https://api.fastgpt.in/api/support/wallet/bill/c
}'
```
**响应结果**
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
data 为 billId,可用于添加知识库数据时进行账单聚合。
...
...
@@ -39,35 +45,30 @@ data 为 billId,可用于添加知识库数据时进行账单聚合。
}
```
## 知识库添加数据
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
## 知识库
{{
<
tabs
tabTotal=
"4"
>
}}
### 创建一个知识库
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
POST
'http
s://api.fastgpt.in/api/core/dataset/data/pushData
'
\
--header
'Authorization: Bearer
apikey
'
\
curl
--location
--request
POST
'http
://localhost:3000/api/core/dataset/create
'
\
--header
'Authorization: Bearer
{{authorization}}
'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"collectionId": "64663f451ba1676dbdef0499",
"trainingMode": "chunk",
"prompt": "可选。qa 拆分引导词,chunk 模式下忽略",
"billId": "可选。如果有这个值,本次的数据会被聚合到一个订单中,这个值可以重复使用。可以参考 [创建训练订单] 获取该值。",
"data": [
{
"q": "你是谁?",
"a": "我是FastGPT助手"
},
{
"q": "你会什么?",
"a": "我什么都会",
"indexes": [{
"type":"custom",
"text":"你好"
}]
}
]
"parentId": null,
"type": "dataset",
"name":"测试",
"intro":"介绍",
"avatar": "",
"vectorModel": "text-embedding-ada-002",
"agentModel": "gpt-3.5-turbo-16k"
}'
```
...
...
@@ -77,101 +78,229 @@ curl --location --request POST 'https://api.fastgpt.in/api/core/dataset/data/pus
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
需要先了解 FastGPT 的多路索引概念:
{{% alert icon=" " context="success" %}}
-
parentId - 父级ID,用于构建目录结构。通常可以为 null 或者直接不传。
-
type -
`dataset`
或者
`folder`
,代表普通知识库和文件夹。不传则代表创建普通知识库。
-
name - 知识库名(必填)
-
intro - 介绍(可选)
-
avatar - 头像地址(可选)
-
vectorModel - 向量模型(建议传空,用系统默认的)
-
agentModel - 文本处理模型(建议传空,用系统默认的)
{{% /alert %}}
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
```
json
{
"code"
:
200
,
"statusText"
:
""
,
"message"
:
""
,
"data"
:
"65abc9bd9d1448617cba5e6c"
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
### 获取知识库列表
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
GET
'http://localhost:3000/api/core/dataset/list?parentId='
\
--header
'Authorization: Bearer {{authorization}}'
\
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
{{% alert icon=" " context="success" %}}
-
parentId - 父级ID,不传或为空,代表获取根目录下的知识库
{{% /alert %}}
在 FastGPT 中,你可以为一组数据创建多个索引,如果不指定索引,则系统会自动取对应的 chunk 作为索引。例如前面的请求示例中:
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
`q:你是谁?a:我是FastGPT助手`
它的
`indexes`
属性为空,意味着不自定义索引,而是使用默认的索引(你是谁?
\n
我是FastGPT助手)。
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
在第二组数据中
`q:你会什么?a:我什么都会`
指定了一个
`你好`
的索引,因此这组数据的索引为
`你好`
。
```json
{
"co
llectionId"
:
"文件集合的ID,参考上面的第二张图"
,
"
mode"
:
"chunk | qa "
,
//
chunk
模式
:
可自定义索引。qa
模型:无法自定义索引,会自动取
data
中的
q
作为数据,让模型自动生成问答对和索引。
"
prompt"
:
"QA 拆分提示词,需严格按照模板,建议不要传入。
"
,
"co
de": 200
,
"
statusText": "",
"
message": "
",
"data": [
{
"q"
:
"生成索引的内容,index 模式下最大 tokens 为3000,建议不超过 1000"
,
"a"
:
"预期回答/补充"
,
"indexes"
:
"自定义索引"
,
},
{
"q"
:
"xxx"
,
"a"
:
"xxxx"
"_id": "65abc9bd9d1448617cba5e6c",
"parentId": null,
"avatar": "",
"name": "测试",
"intro": "",
"type": "dataset",
"permission": "private",
"canWrite": true,
"isOwner": true,
"vectorModel": {
"model": "text-embedding-ada-002",
"name": "Embedding-2",
"inputPrice": 0,
"defaultToken": 512,
"maxToken": 8000,
"weight": 100
}
}
],
]
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
{{
<
tab
tabName=
"响应例子"
>
}}
### 获取知识库详情
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
GET
'http://localhost:3000/api/core/dataset/detail?id=6593e137231a2be9c5603ba7'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
{{% alert icon=" " context="success" %}}
-
id: 知识库的ID
{{% /alert %}}
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
```json
{
"code": 200,
"statusText": "",
"message": "",
"data": {
"insertLen"
:
1
,
//
最终插入成功的数量
"overToken"
:
[],
//
超出
token
的
"repeat"
:
[],
//
重复的数量
"error"
:
[]
//
其他错误
"_id": "6593e137231a2be9c5603ba7",
"parentId": null,
"teamId": "65422be6aa44b7da77729ec8",
"tmbId": "65422be6aa44b7da77729ec9",
"type": "dataset",
"status": "active",
"avatar": "/icon/logo.svg",
"name": "FastGPT test",
"vectorModel": {
"model": "text-embedding-ada-002",
"name": "Embedding-2",
"inputPrice": 0,
"defaultToken": 512,
"maxToken": 8000,
"weight": 100
},
"agentModel": {
"model": "gpt-3.5-turbo-16k",
"name": "FastAI-16k",
"maxContext": 16000,
"maxResponse": 16000,
"inputPrice": 0,
"outputPrice": 0
},
"intro": "",
"permission": "private",
"updateTime": "2024-01-02T10:11:03.084Z",
"canWrite": true,
"isOwner": true
}
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
{{
<
tab
tabName=
"QA Prompt 模板"
>
}}
{{
<
markdownify
>
}}
### 删除一个知识库
{{theme}} 里的内容可以换成数据的主题。默认为:它们可能包含多个主题内容
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
DELETE
'http://localhost:3000/api/core/dataset/delete?id=65abc8729d1448617cba5df6'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
我会给你一段文本,{{theme}},学习它们,并整理学习成果,要求为:
1. 提出最多 25 个问题。
2. 给出每个问题的答案。
3. 答案要详细完整,答案可以包含普通文字、链接、代码、表格、公示、媒体链接等 markdown 元素。
4. 按格式返回多个问题和答案:
Q1: 问题。
A1: 答案。
Q2:
A2:
……
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
我的文本:"""{{text}}"""
```
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
{{% alert icon=" " context="success" %}}
-
id: 知识库的ID
{{% /alert %}}
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
```json
{
"code": 200,
"statusText": "",
"message": "",
"data": null
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
## 搜索测试
## 集合
### 创建一个空的集合
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
POST
'http
s://api.fastgpt.in/api/core/dataset/searchTest
'
\
--header
'Authorization: Bearer
fastgpt-xxxxx
'
\
curl
--location
--request
POST
'http
://localhost:3000/api/core/dataset/collection/create
'
\
--header
'Authorization: Bearer
{{authorization}}
'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"datasetId": "知识库的ID",
"text": "导演是谁",
"limit": 5000,
"similarity": 0,
"searchMode": "embedding",
"usingReRank": false
"datasetId":"6593e137231a2be9c5603ba7",
"parentId": null,
"name":"测试",
"type":"virtual",
"metadata":{
"test":111
}
}'
```
...
...
@@ -181,12 +310,15 @@ curl --location --request POST 'https://api.fastgpt.in/api/core/dataset/searchTe
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
-
datasetId - 知识库ID
-
text - 需要测试的文本
-
limit - 最大 tokens 数量
-
similarity - 最低相关度(0~1,可选)
-
searchMode - 搜索模式:embedding | fullTextRecall | mixedRecall
-
usingReRank - 使用重排
{{% alert icon=" " context="success" %}}
-
datasetId: 知识库的ID(必填)
-
parentId: 父级ID,不填则默认为根目录
-
name: 集合名称(必填)
-
type:
-
folder:文件夹
-
virtual:虚拟集合(手动集合)
-
metadata: 元数据(暂时没啥用)
{{% /alert %}}
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
...
...
@@ -194,71 +326,76 @@ curl --location --request POST 'https://api.fastgpt.in/api/core/dataset/searchTe
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
返回 top k 结果, limit 为最大 Tokens 数量,最多 20000 tokens
。
data 为集合的 ID
。
```
bash
```
json
{
"code"
:
200
,
"statusText"
:
""
,
"data"
:
[
{
"id"
:
"65599c54a5c814fb803363cb"
,
"q"
:
"你是谁"
,
"a"
:
"我是FastGPT助手"
,
"datasetId"
:
"6554684f7f9ed18a39a4d15c"
,
"collectionId"
:
"6556cd795e4b663e770bb66d"
,
"sourceName"
:
"GBT 15104-2021 装饰单板贴面人造板.pdf"
,
"sourceId"
:
"6556cd775e4b663e770bb65c"
,
"score"
: 0.8050316572189331
}
,
......
]
"message"
:
""
,
"data"
:
"65abcd009d1448617cba5ee1"
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
#
更多接口
#
## 创建一个纯文本集合(商业版)
目前未整理,简陋导出:
传入一段文字,创建一个集合,会根据传入的文字进行分割。
## POST 知识库搜索测试
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
POST /core/dataset/searchTest
```
bash
curl
--location
--request
POST
'http://localhost:3000/api/proApi/core/dataset/collection/create/text'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"text":"xxxxxxxx",
"datasetId":"6593e137231a2be9c5603ba7",
"parentId": null,
"name":"测试训练",
> Body Parameters
"trainingType": "qa",
"chunkSize":8000,
"chunkSplitter":"",
"qaPrompt":"11",
```
json
{
"datasetId"
:
"656c2ccff7f114064daa72f6"
,
"text"
:
"导演是谁"
,
"limit"
:
1500
,
"searchMode"
:
"embedding"
,
"usingReRank"
:
true
,
"similarity"
:
0.5
}
"metadata":{}
}'
```
### Params
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
{{% alert icon=" " context="success" %}}
-
text: 原文本
-
datasetId: 知识库的ID(必填)
-
parentId: 父级ID,不填则默认为根目录
-
name: 集合名称(必填)
-
metadata: 元数据(暂时没啥用)
-
trainingType:(必填)
-
chunk: 按文本长度进行分割
-
qa: QA拆分
-
chunkSize: 每个 chunk 的长度(可选). chunk模式:100~3000; qa模式: 4000~模型最大token(16k模型通常建议不超过10000)
-
chunkSplitter: 自定义最高优先分割符号(可选)
-
qaPrompt: qa拆分自定义提示词(可选)
{{% /alert %}}
|Name|Location|Type|Required|Description|
|---|---|---|---|---|
|Authorization|header|string| no |none|
|body|body|object| no |none|
|» datasetId|body|string| yes |none|
|» text|body|string| yes |none|
|» limit|body|integer| no |none|
|» searchMode|body|
[
search mode
](
#schemasearch%20mode
)
| yes |none|
|» usingReRank|body|boolean| no |none|
|» similarity|body|
[
similary
](
#schemasimilary
)
| no |none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
> Response Examples
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> 成功
data 为集合的 ID。
```
json
{
...
...
@@ -266,1110 +403,795 @@ POST /core/dataset/searchTest
"statusText"
:
""
,
"message"
:
""
,
"data"
:
{
"list"
:
[
{
"id"
:
"65962b23f5fac58e46330dfd"
,
"q"
:
"# 快速了解 FastGPT
\n
FastGPT 的能力与优势
\n\n
FastGPT 是一个基于 LLM 大语言模型的知识库问答系统,提供开箱即用的数据处理、模型调用等能力。同时可以通过 Flow 可视化进行工作流编排,从而实现复杂的问答场景!
\n\n
🤖
\n\n
FastGPT 在线使用:[https://fastgpt.in](https://fastgpt.in)
\n\n
| | |
\n
| --- | --- |
\n
|  | 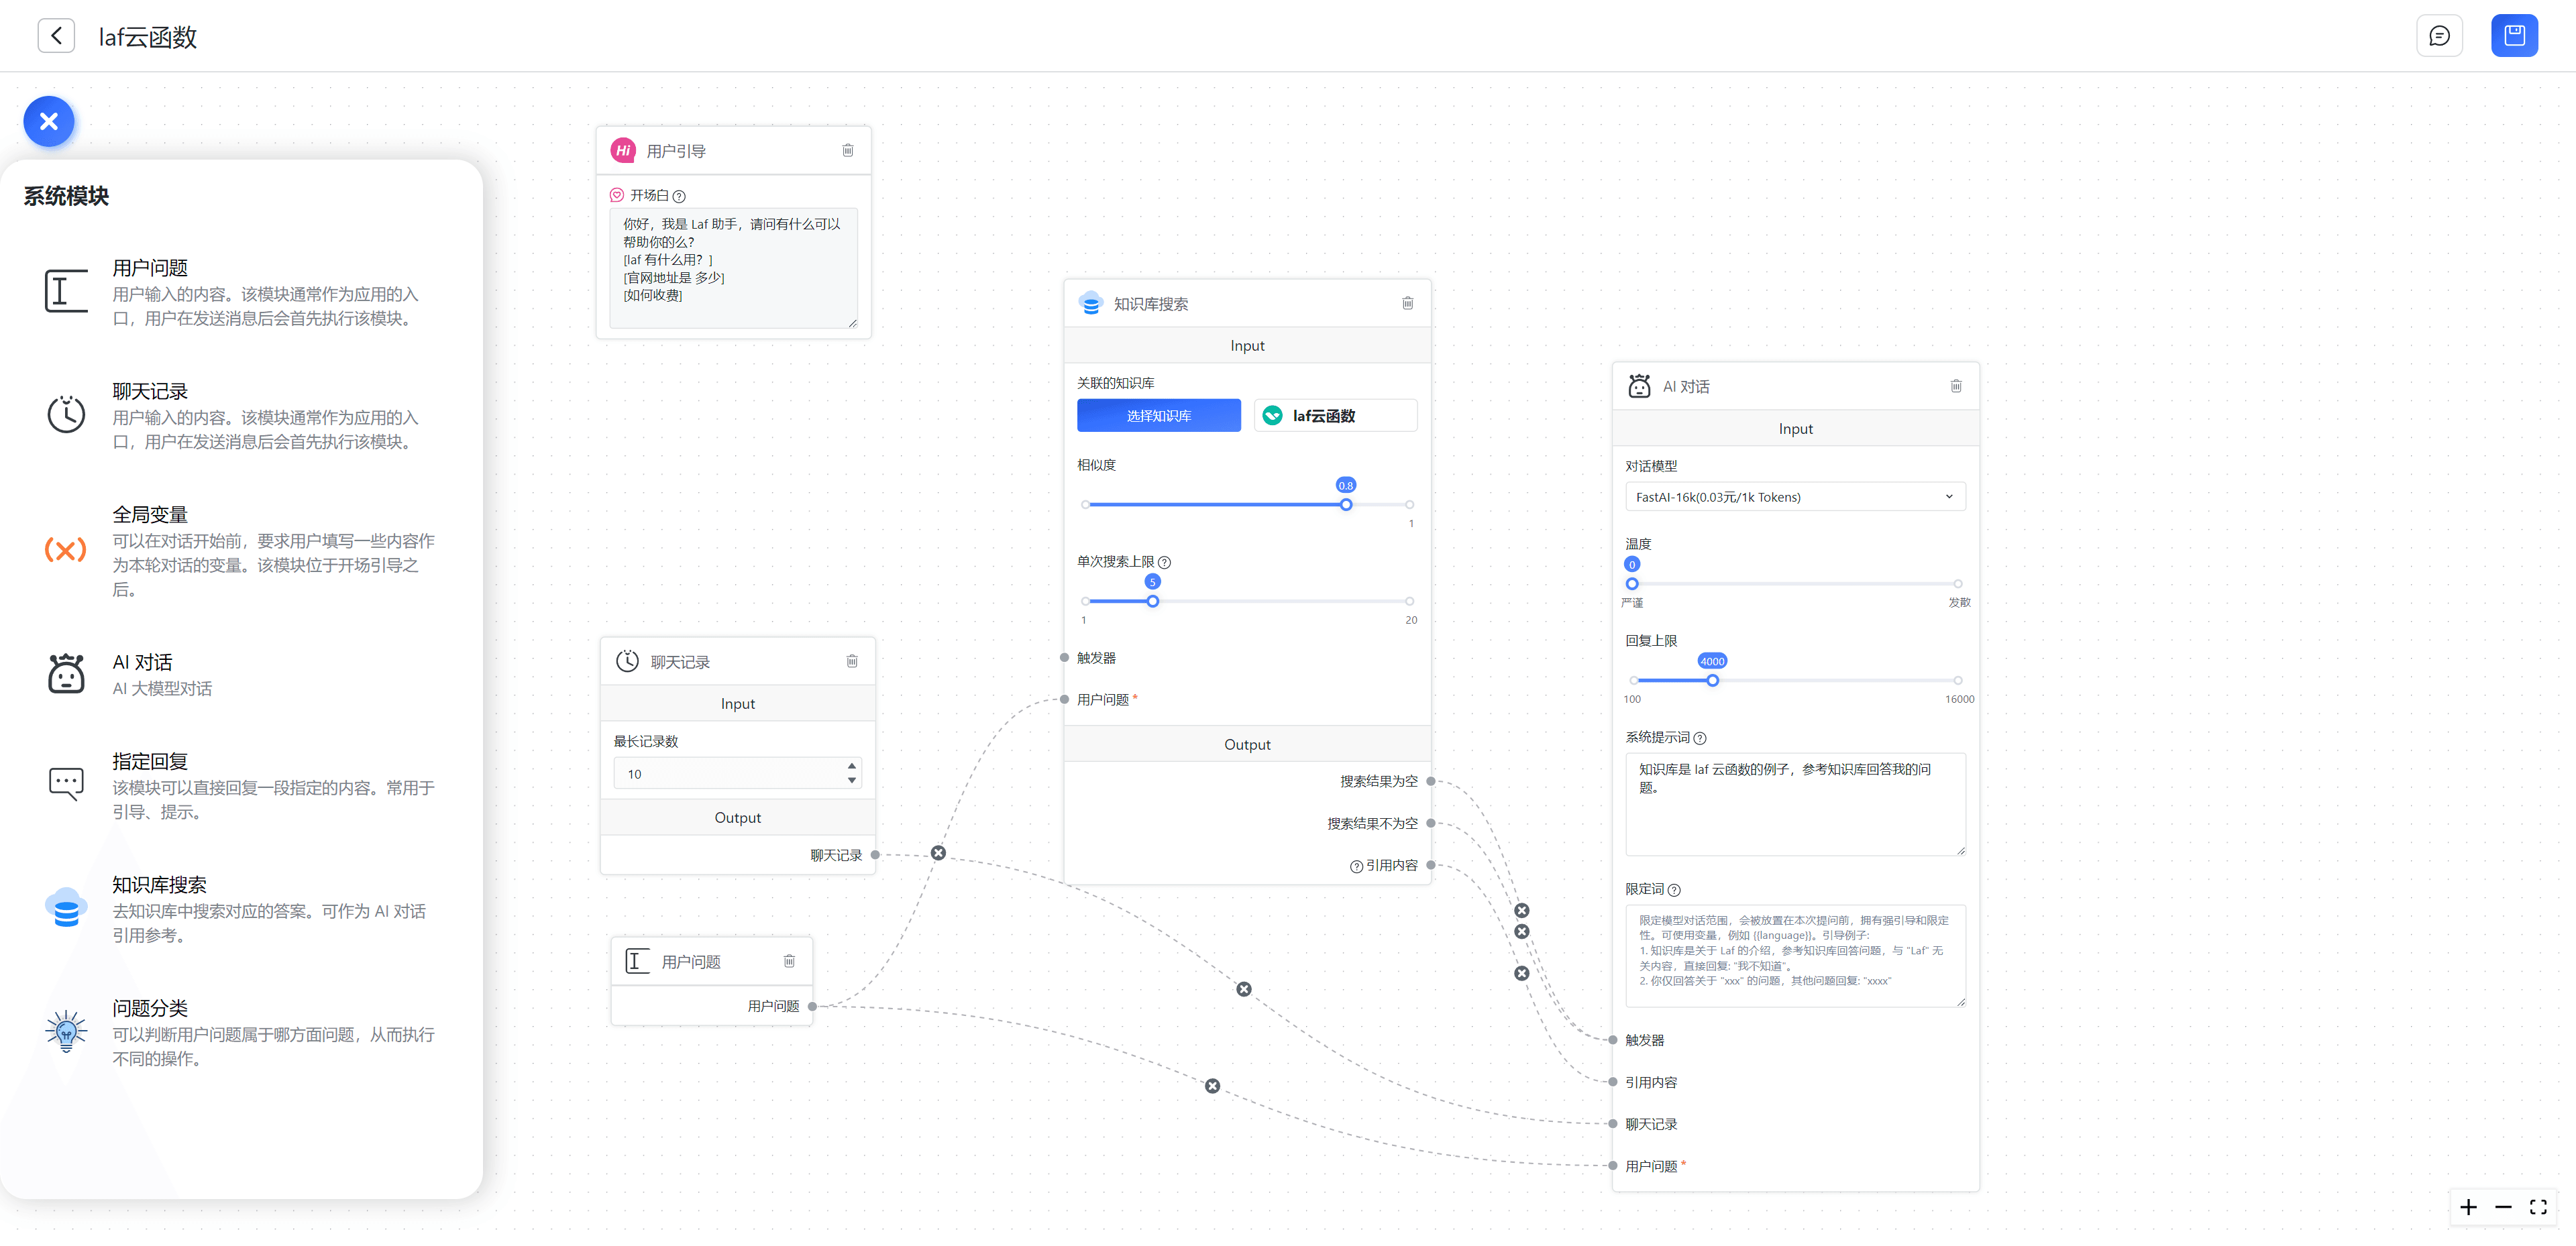 |
\n
| 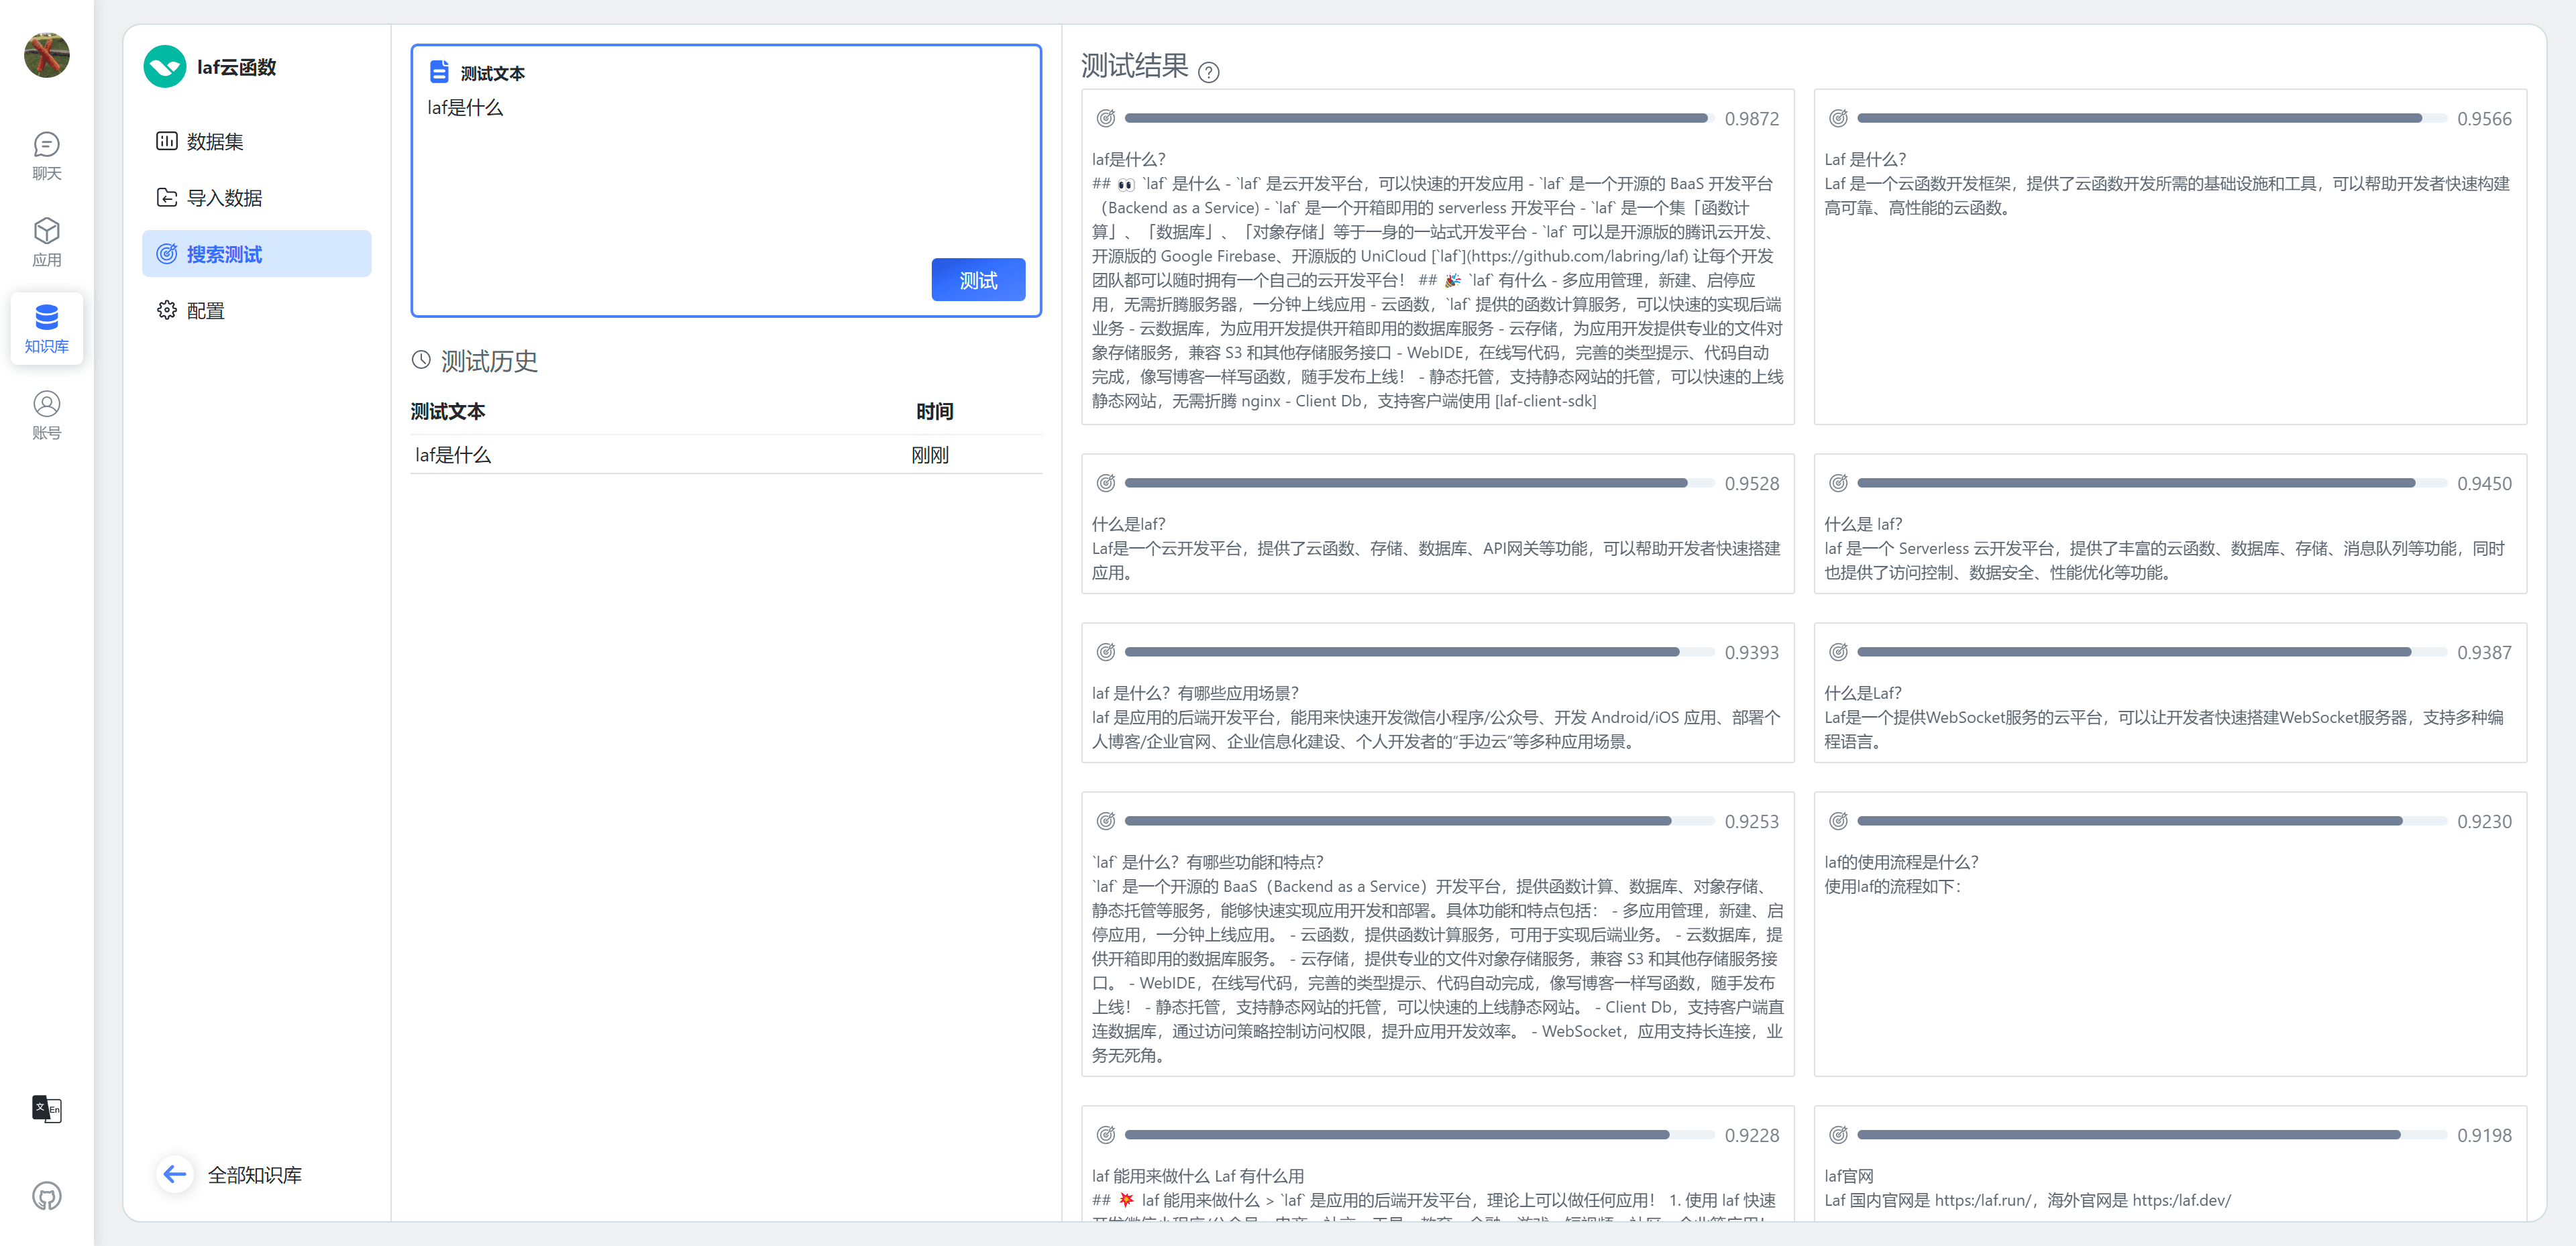 | 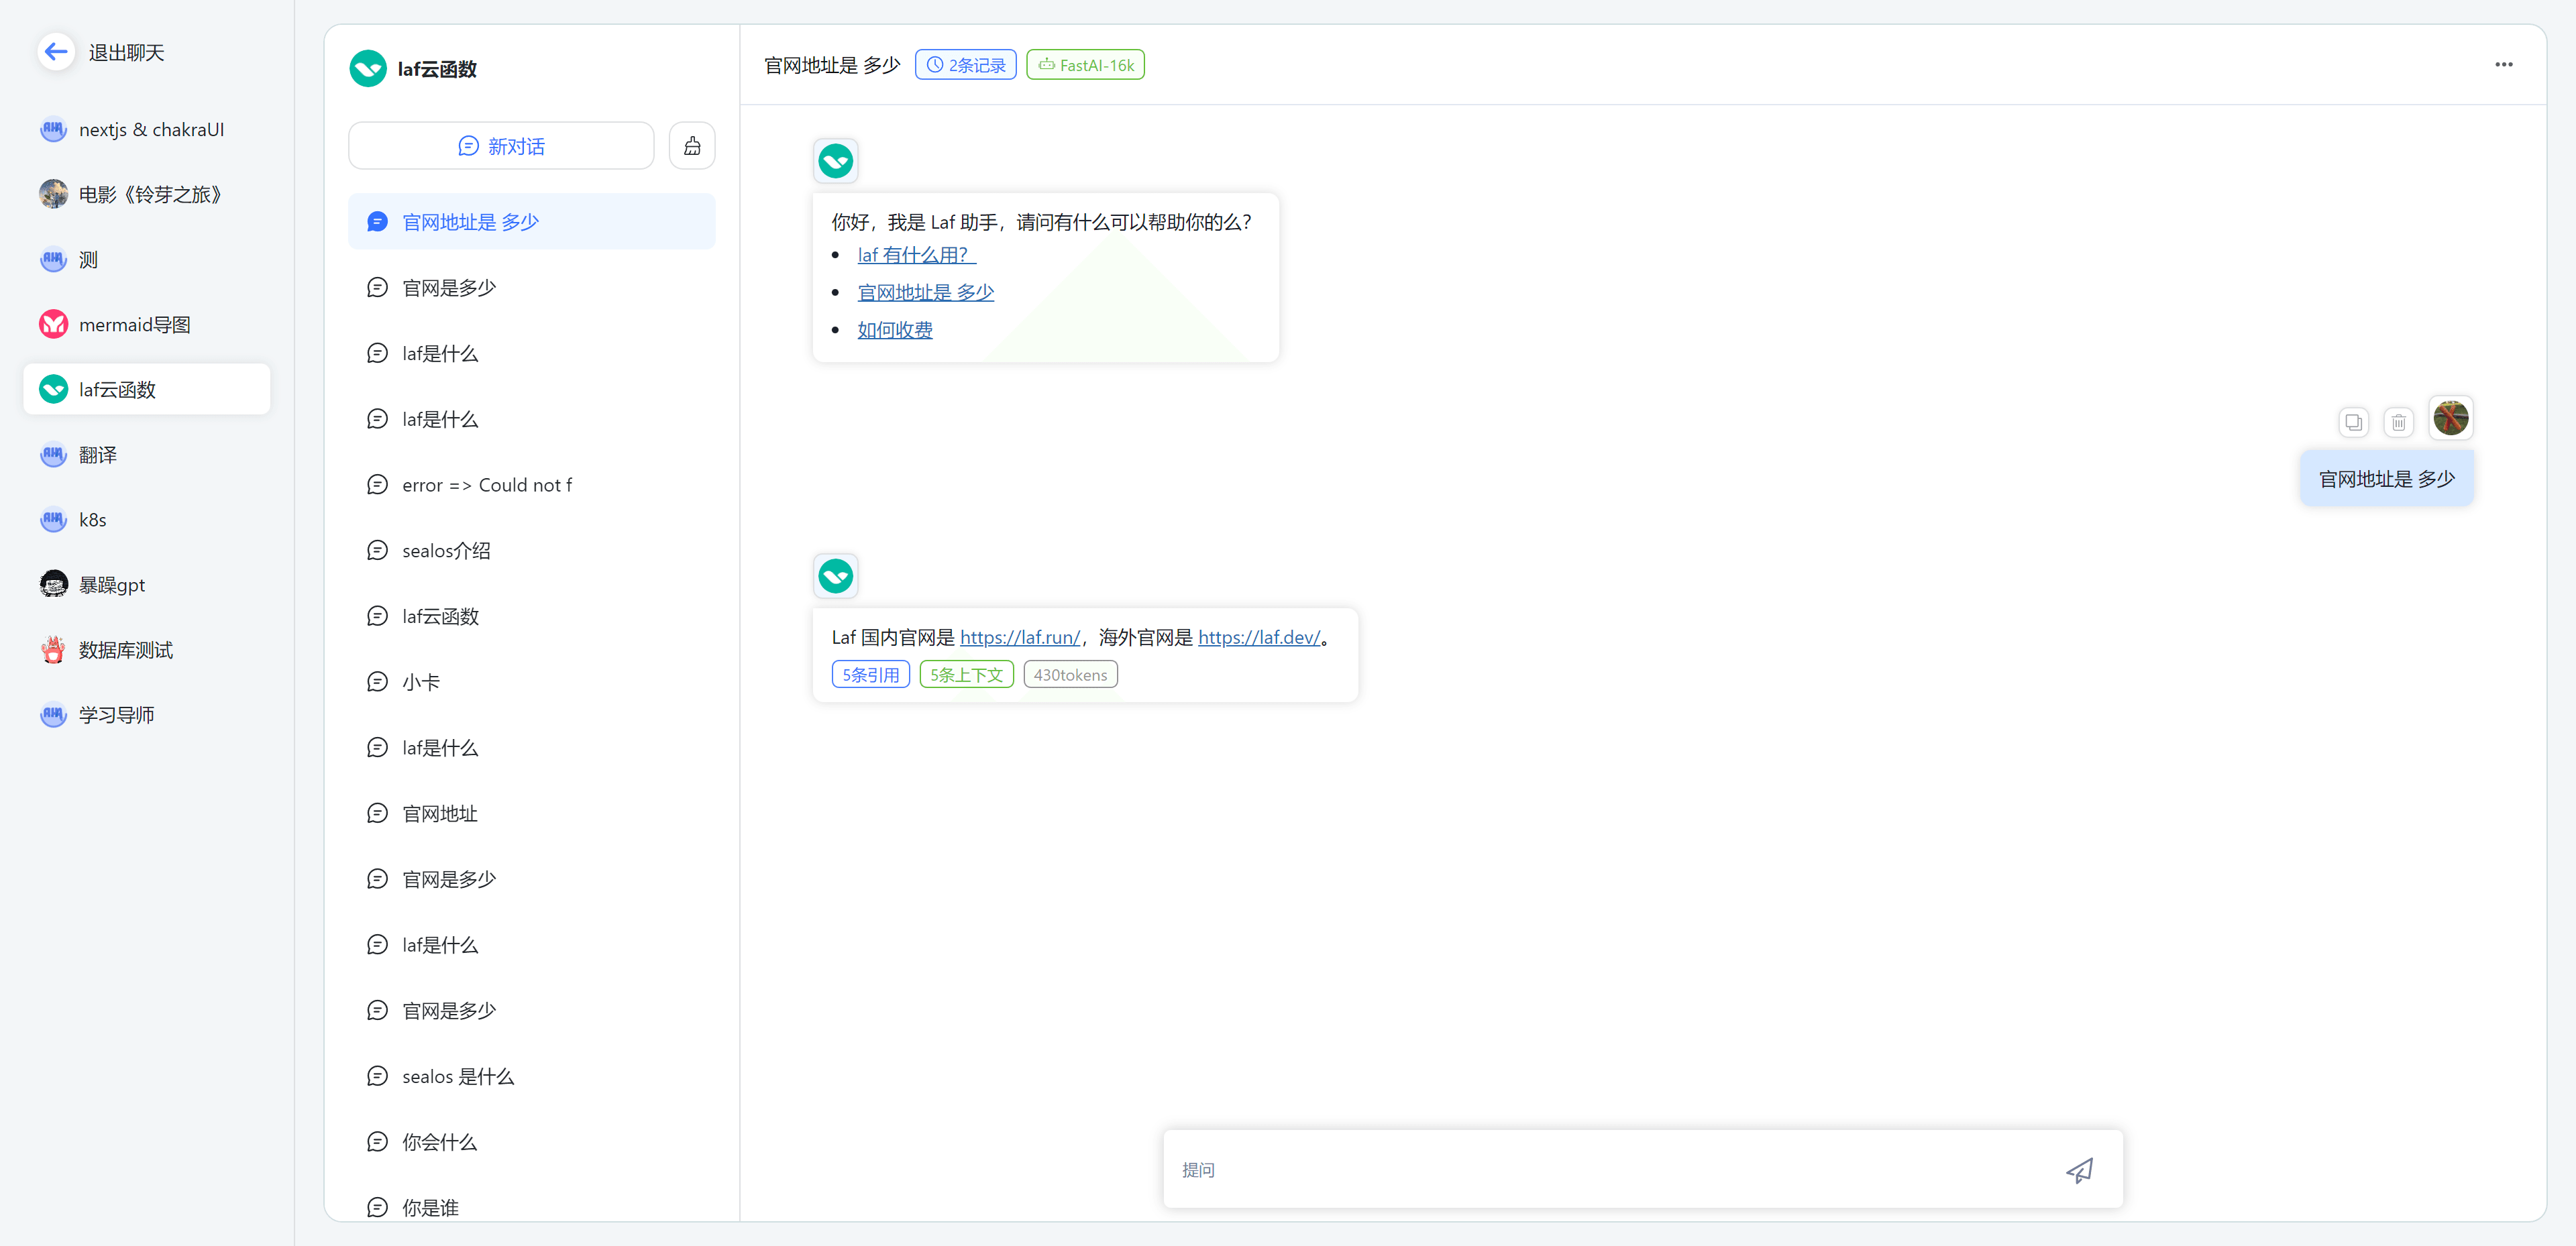 |
\n\n
"
,
"a"
:
""
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65962b2089642fd209da3b03"
,
"sourceName"
:
"https://doc.fastgpt.in/docs/intro/"
,
"sourceId"
:
"https://doc.fastgpt.in/docs/intro/"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8036568760871887
,
"index"
:
20
},
{
"type"
:
"fullText"
,
"value"
:
1.168349443855932
,
"index"
:
2
},
{
"type"
:
"reRank"
,
"value"
:
0.9870296135626316
,
"index"
:
0
},
{
"type"
:
"rrf"
,
"value"
:
0.04366449476962486
,
"index"
:
0
}
]
},
{
"id"
:
"65962b24f5fac58e46330dff"
,
"q"
:
"# 快速了解 FastGPT
\n
## FastGPT 能力
\n
### 2. 简单易用的可视化界面
\n
FastGPT 采用直观的可视化界面设计,为各种应用场景提供了丰富实用的功能。通过简洁易懂的操作步骤,可以轻松完成 AI 客服的创建和训练流程。
\n\n
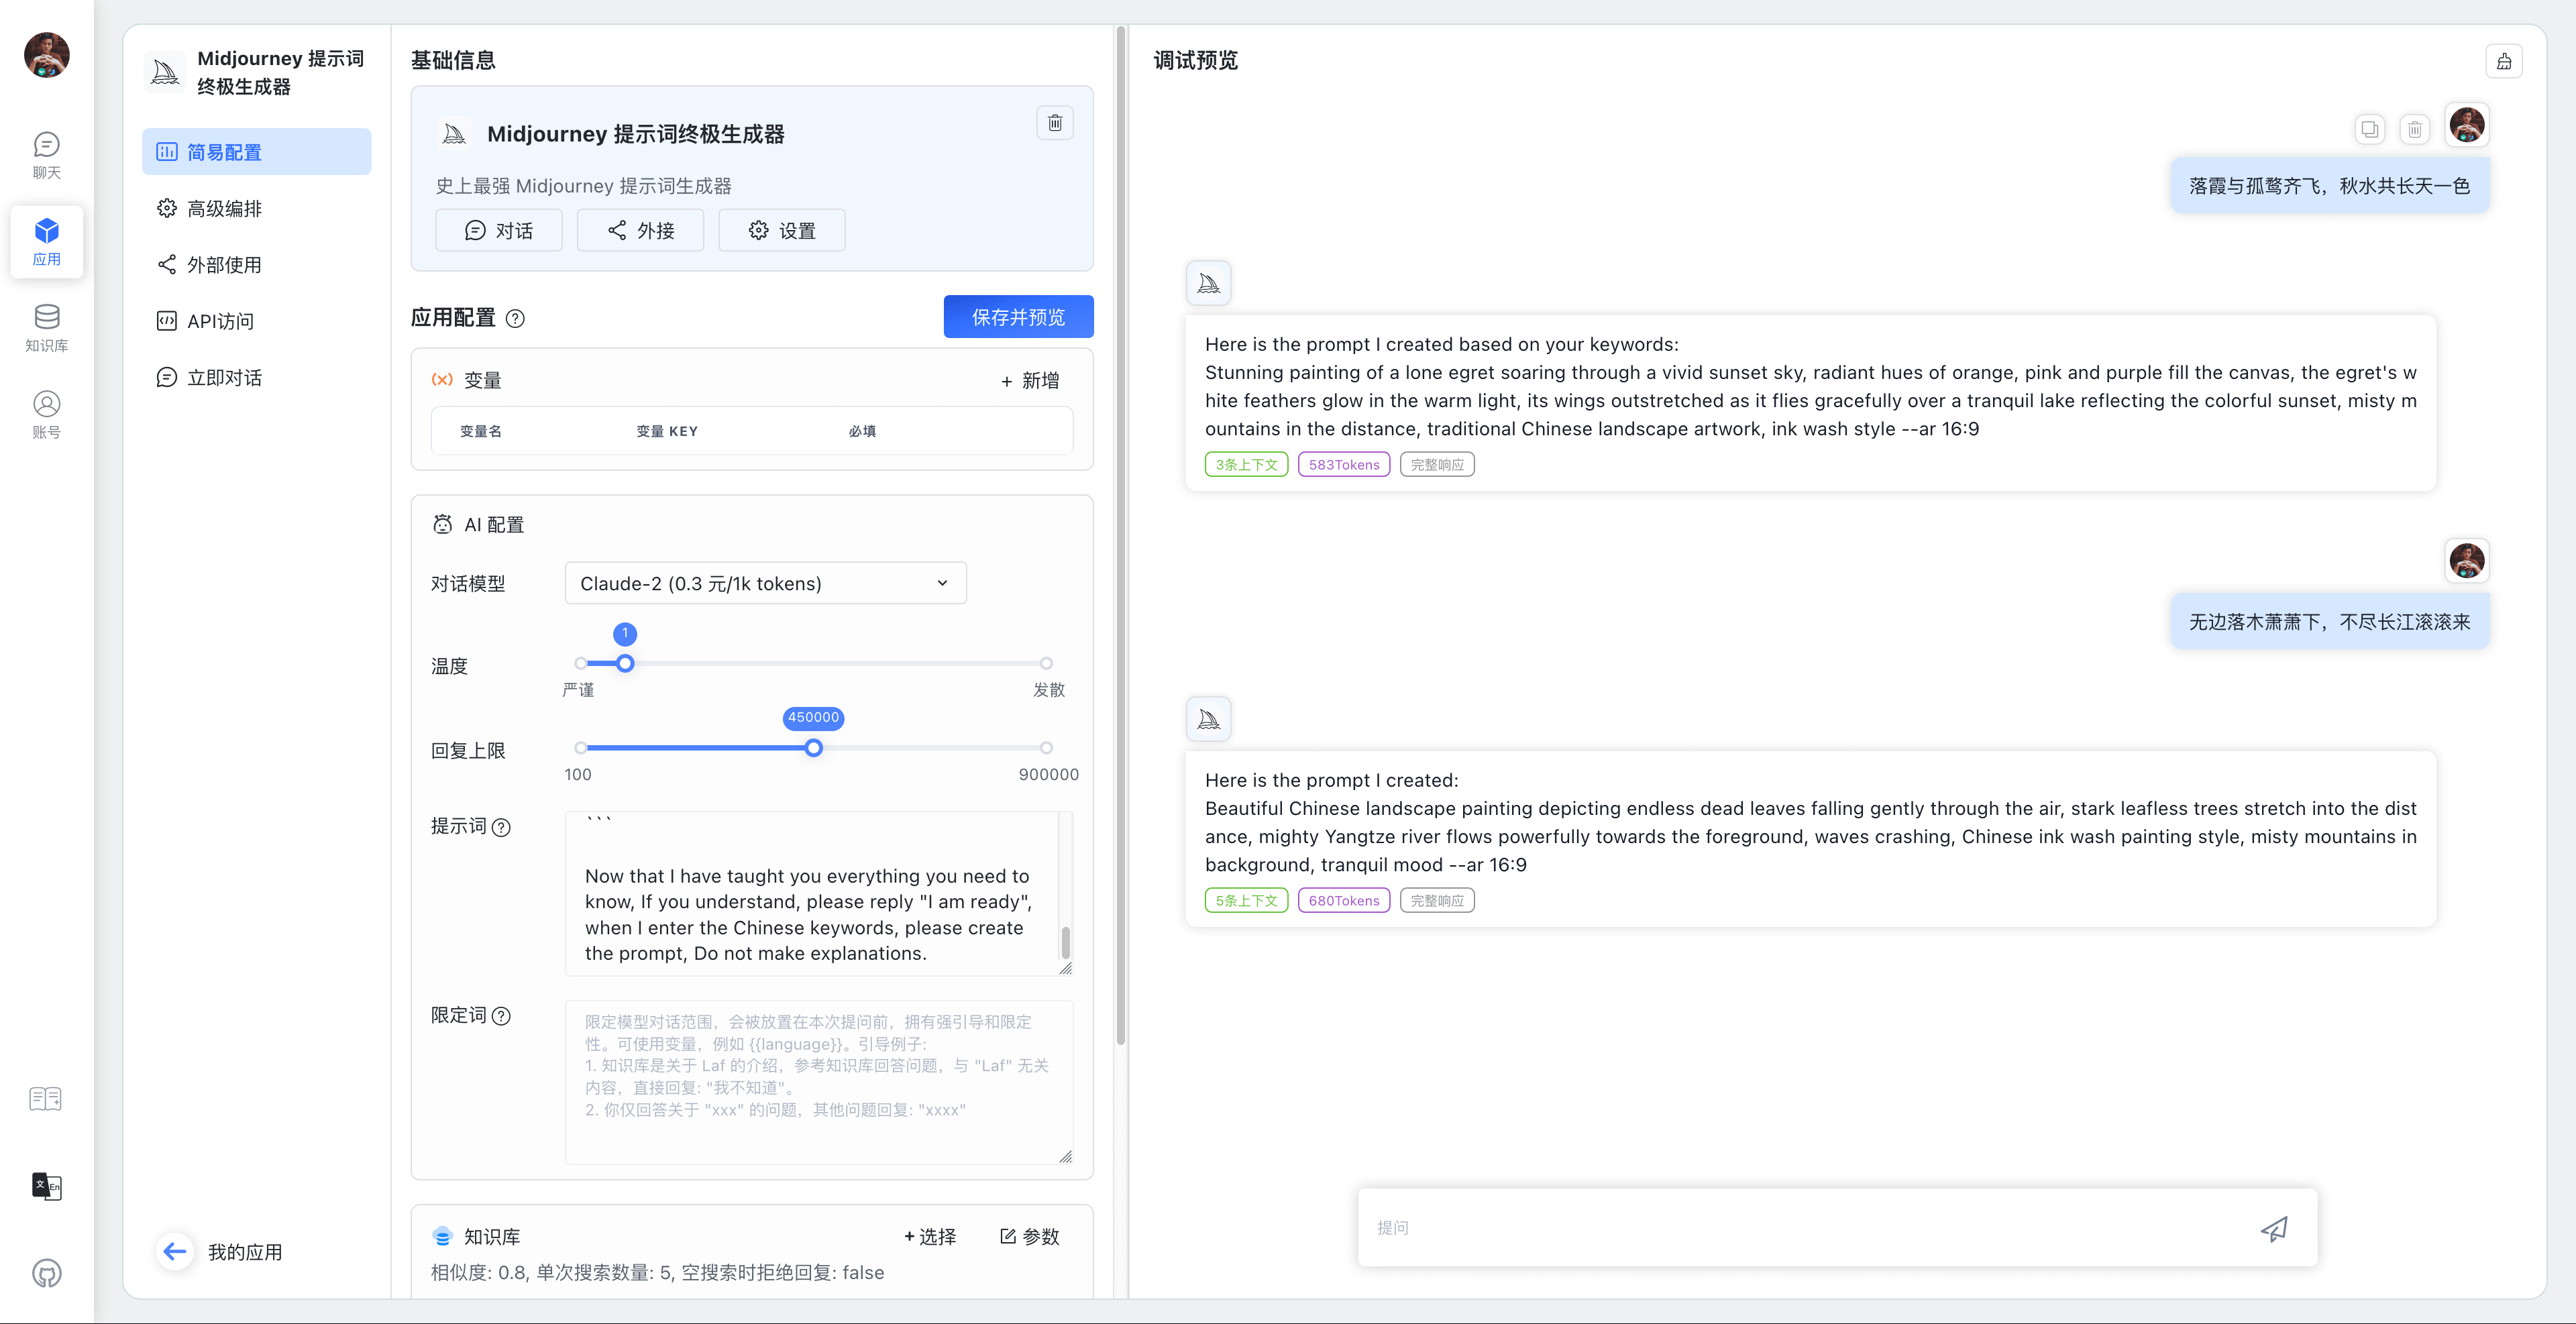
\n\n
"
,
"a"
:
""
,
"chunkIndex"
:
2
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65962b2089642fd209da3b03"
,
"sourceName"
:
"https://doc.fastgpt.in/docs/intro/"
,
"sourceId"
:
"https://doc.fastgpt.in/docs/intro/"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8152669668197632
,
"index"
:
3
},
{
"type"
:
"fullText"
,
"value"
:
1.0511363636363635
,
"index"
:
8
},
{
"type"
:
"reRank"
,
"value"
:
0.9287972729281414
,
"index"
:
14
},
{
"type"
:
"rrf"
,
"value"
:
0.04265696347031964
,
"index"
:
1
}
]
},
{
"id"
:
"65962b25f5fac58e46330e00"
,
"q"
:
"# 快速了解 FastGPT
\n
## FastGPT 能力
\n
### 3. 自动数据预处理
\n
提供手动输入、直接分段、LLM 自动处理和 CSV 等多种数据导入途径,其中“直接分段”支持通过 PDF、WORD、Markdown 和 CSV 文档内容作为上下文。FastGPT 会自动对文本数据进行预处理、向量化和 QA 分割,节省手动训练时间,提升效能。
\n\n
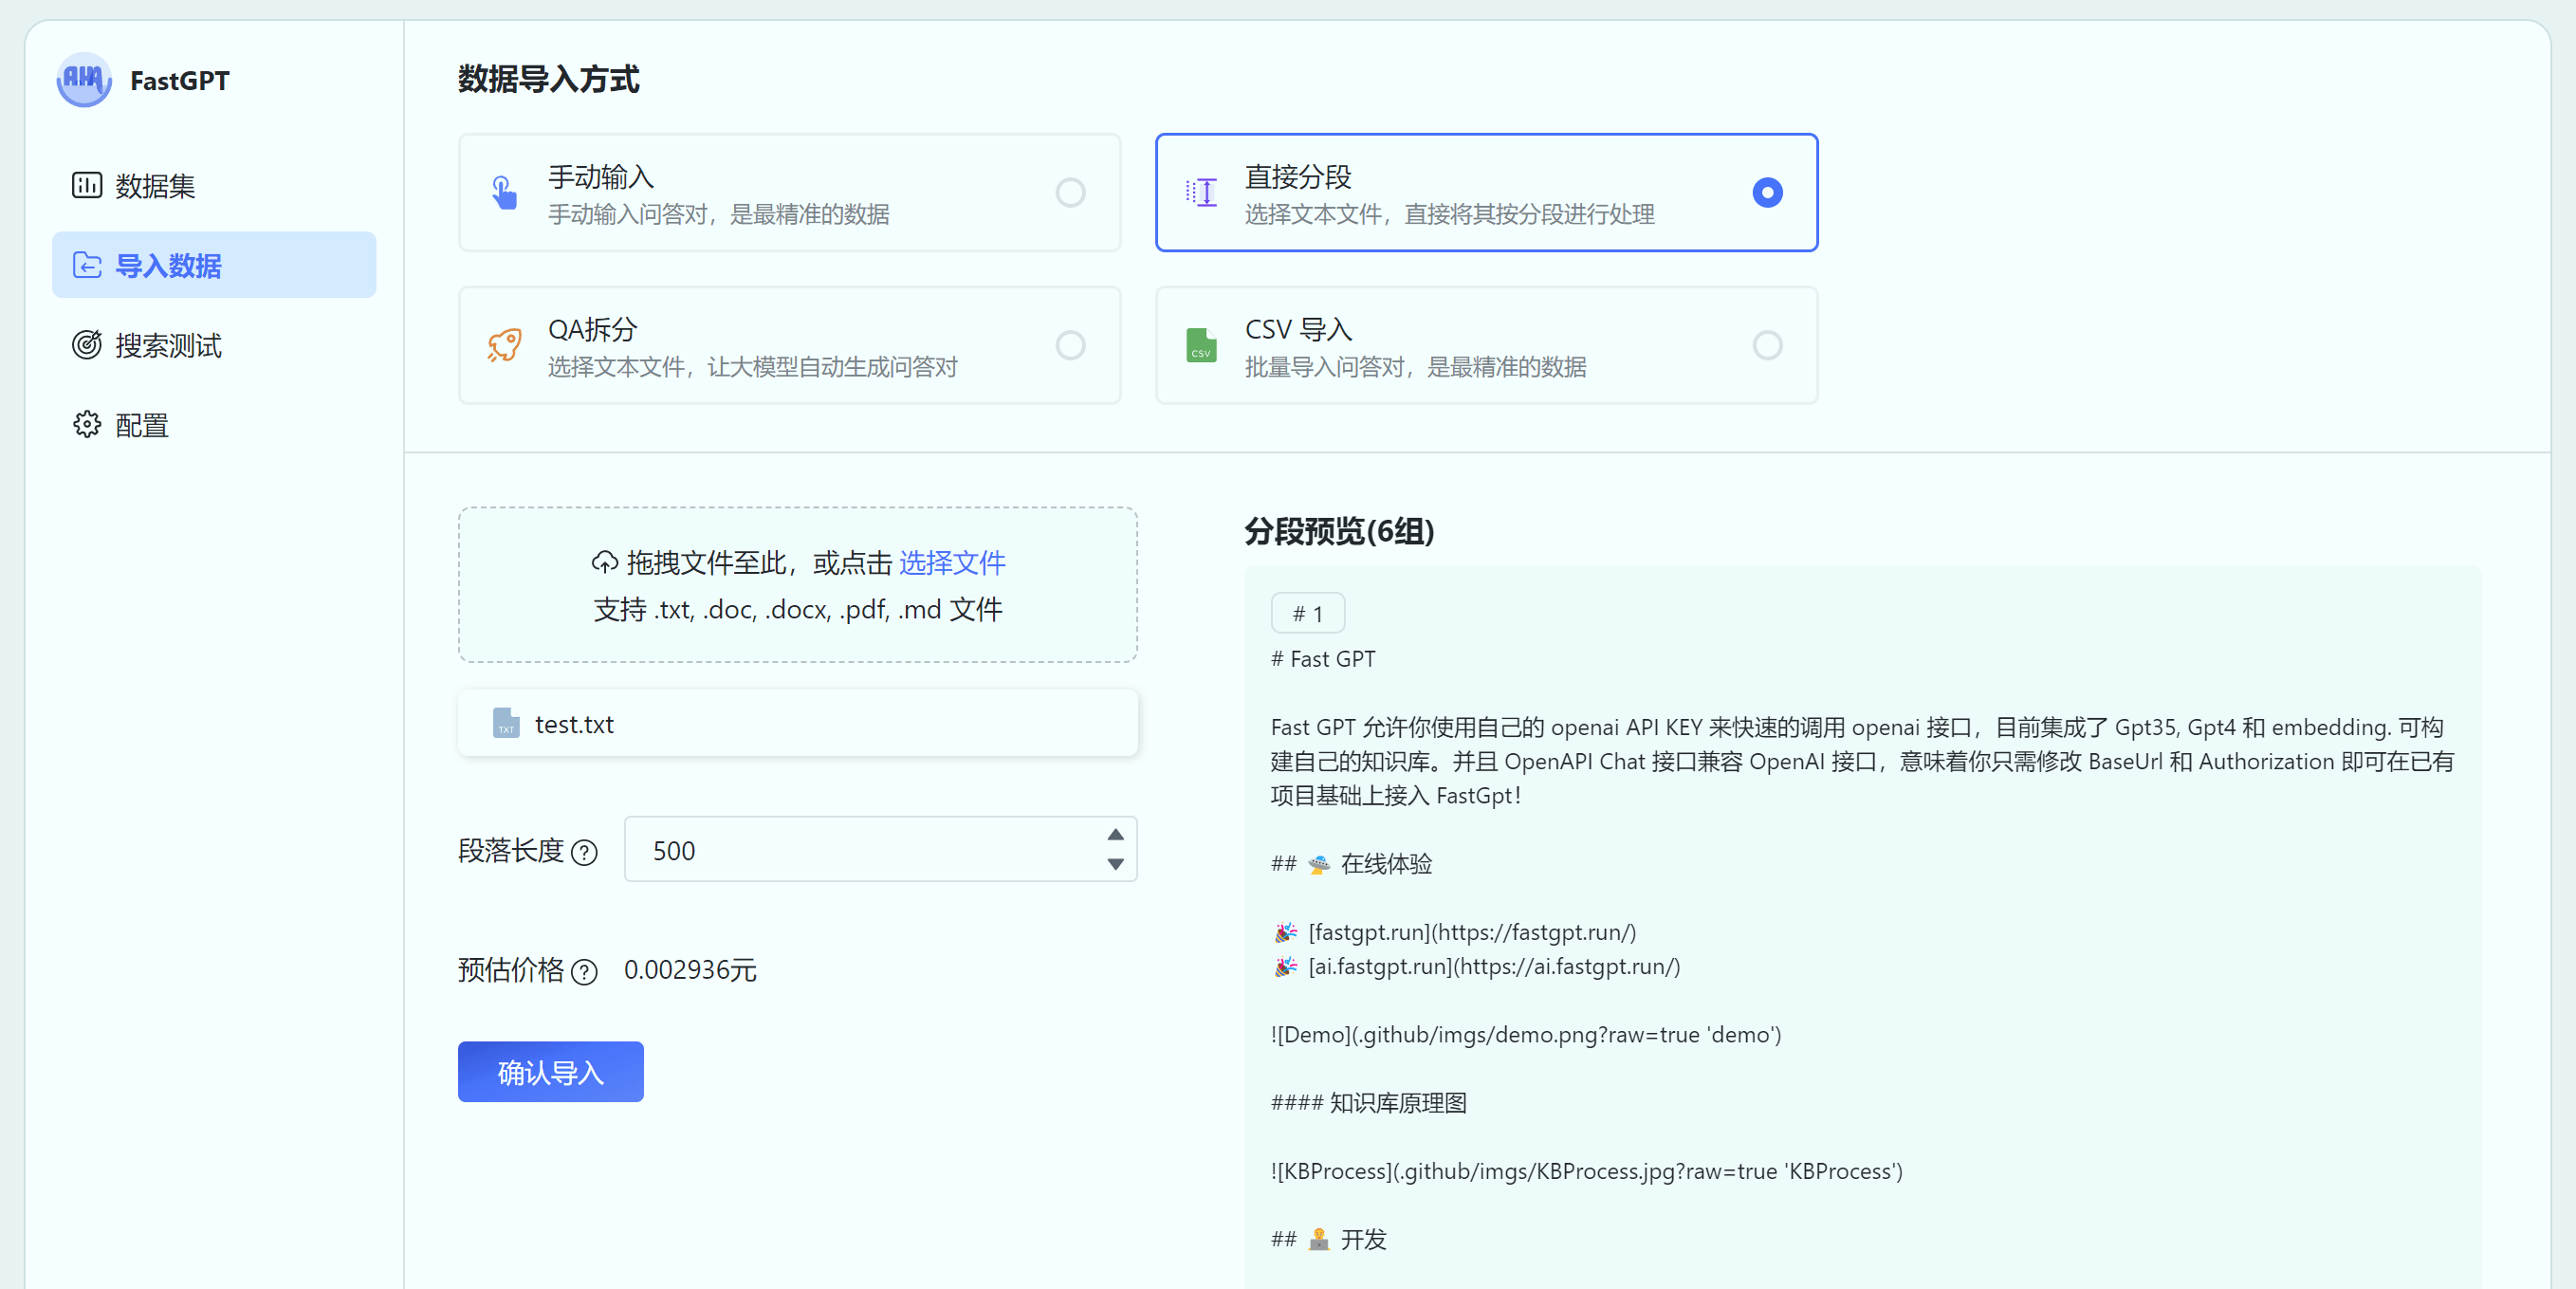
\n\n
"
,
"a"
:
""
,
"chunkIndex"
:
3
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65962b2089642fd209da3b03"
,
"sourceName"
:
"https://doc.fastgpt.in/docs/intro/"
,
"sourceId"
:
"https://doc.fastgpt.in/docs/intro/"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8158369064331055
,
"index"
:
2
},
{
"type"
:
"fullText"
,
"value"
:
1.014030612244898
,
"index"
:
20
},
{
"type"
:
"reRank"
,
"value"
:
0.9064876908461501
,
"index"
:
17
},
{
"type"
:
"rrf"
,
"value"
:
0.04045823457588163
,
"index"
:
2
}
]
},
{
"id"
:
"65a7e1e8fc13bdf20fd46d41"
,
"q"
:
"# 快速了解 FastGPT
\n
## FastGPT 能力
\n
### 5. 强大的 API 集成
\n
FastGPT 对外的 API 接口对齐了 OpenAI 官方接口,可以直接接入现有的 GPT 应用,也可以轻松集成到企业微信、公众号、飞书等平台。
\n\n
"
,
"a"
:
""
,
"chunkIndex"
:
66
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7e1d4fc13bdf20fd46abe"
,
"sourceName"
:
"dataset - 2024-01-04T151625.388.csv"
,
"sourceId"
:
"65a7e1d2fc13bdf20fd46abc"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.803692102432251
,
"index"
:
18
},
{
"type"
:
"fullText"
,
"value"
:
1.0511363636363635
,
"index"
:
7
},
{
"type"
:
"reRank"
,
"value"
:
0.9177460552422909
,
"index"
:
15
},
{
"type"
:
"rrf"
,
"value"
:
0.03970501147383226
,
"index"
:
3
}
]
},
{
"id"
:
"65a7be319d96e21823f69c9b"
,
"q"
:
"FastGPT Flow 的工作流设计方案提供了哪些操作?"
,
"a"
:
"FastGPT Flow 的工作流设计方案提供了数据预处理、各类 AI 应用设置、调试测试及结果反馈等操作。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8283981680870056
,
"index"
:
0
},
{
"type"
:
"reRank"
,
"value"
:
0.9620363047907355
,
"index"
:
4
},
{
"type"
:
"rrf"
,
"value"
:
0.03177805800756621
,
"index"
:
4
}
]
},
{
"id"
:
"65a7be389d96e21823f69d58"
,
"q"
:
"FastGPT Flow 的实验室预约示例中使用了哪些参数?"
,
"a"
:
"FastGPT Flow 的实验室预约示例中使用了姓名、时间和实验室名称等参数。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8143455386161804
,
"index"
:
9
},
{
"type"
:
"reRank"
,
"value"
:
0.9806919138043485
,
"index"
:
1
},
{
"type"
:
"rrf"
,
"value"
:
0.0304147465437788
,
"index"
:
5
}
]
},
{
"id"
:
"65a7be309d96e21823f69c78"
,
"q"
:
"FastGPT Flow 是什么?"
,
"a"
:
"FastGPT Flow 是一款基于大型语言模型的知识库问答系统,通过引入 Flow 可视化工作流编排技术,提供了一个即插即用的解决方案。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8115077018737793
,
"index"
:
11
},
{
"type"
:
"reRank"
,
"value"
:
0.9686195704870232
,
"index"
:
3
},
{
"type"
:
"rrf"
,
"value"
:
0.029513888888888888
,
"index"
:
6
}
]
},
{
"id"
:
"65a7be389d96e21823f69d5e"
,
"q"
:
"FastGPT Flow 的实验室预约示例中的代码实现了哪些功能?"
,
"a"
:
"FastGPT Flow 的实验室预约示例中的代码实现了预约实验室、修改预约、查询预约和取消预约等功能。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8166953921318054
,
"index"
:
1
},
{
"type"
:
"reRank"
,
"value"
:
0.8350804533361768
,
"index"
:
20
},
{
"type"
:
"rrf"
,
"value"
:
0.028474711270410194
,
"index"
:
8
}
]
},
{
"id"
:
"65a7be389d96e21823f69d4f"
,
"q"
:
"FastGPT Flow 的联网搜索示例中使用了哪些参数?"
,
"a"
:
"FastGPT Flow 的联网搜索示例中使用了搜索关键词、Google 搜索的 API 密钥和自定义搜索引擎 ID。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8025297522544861
,
"index"
:
21
},
{
"type"
:
"reRank"
,
"value"
:
0.9730876959261983
,
"index"
:
2
},
{
"type"
:
"rrf"
,
"value"
:
0.028068137824235385
,
"index"
:
10
}
]
},
{
"id"
:
"65a7e1e8fc13bdf20fd46d55"
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7e1d4fc13bdf20fd46abe"
,
"sourceName"
:
"dataset - 2024-01-04T151625.388.csv"
,
"sourceId"
:
"65a7e1d2fc13bdf20fd46abc"
,
"q"
:
"# 快速了解 FastGPT
\n
## FastGPT 特点
\n
1. **项目开源**
\n
\n
FastGPT 遵循附加条件 Apache License 2.0 开源协议,你可以 [Fork](https://github.com/labring/FastGPT/fork) 之后进行二次开发和发布。FastGPT 社区版将保留核心功能,商业版仅在社区版基础上使用 API 的形式进行扩展,不影响学习使用。
\n
\n
2. **独特的 QA 结构**
\n
\n
针对客服问答场景设计的 QA 结构,提高在大量数据场景中的问答准确性。
\n
\n
3. **可视化工作流**
\n
\n
通过 Flow 模块展示了从问题输入到模型输出的完整流程,便于调试和设计复杂流程。
\n
\n
4. **无限扩展**
\n
\n
基于 API 进行扩展,无需修改 FastGPT 源码,也可快速接入现有的程序中。
\n
\n
5. **便于调试**
\n
\n
提供搜索测试、引用修改、完整对话预览等多种调试途径。
\n
\n
6. **支持多种模型**
\n
\n
支持 GPT、Claude、文心一言等多种 LLM 模型,未来也将支持自定义的向量模型。"
,
"a"
:
""
,
"chunkIndex"
:
67
,
"score"
:
[
{
"type"
:
"fullText"
,
"value"
:
1.0340073529411764
,
"index"
:
12
},
{
"type"
:
"reRank"
,
"value"
:
0.9542227274192233
,
"index"
:
9
},
{
"type"
:
"rrf"
,
"value"
:
0.027272727272727275
,
"index"
:
11
}
]
},
{
"id"
:
"65a7be319d96e21823f69c8f"
,
"q"
:
"FastGPT Flow 的工作流设计中,模块之间如何进行组合和组装?"
,
"a"
:
"FastGPT Flow 允许用户在核心工作流模块中进行自由组合和组装,从而衍生出一个新的模块。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8098832368850708
,
"index"
:
13
},
{
"type"
:
"reRank"
,
"value"
:
0.9478657435317039
,
"index"
:
12
},
{
"type"
:
"rrf"
,
"value"
:
0.027212143650499815
,
"index"
:
12
}
]
},
{
"id"
:
"65a7be359d96e21823f69ce0"
,
"q"
:
"FastGPT Flow 的模块的输入和输出如何连接?"
,
"a"
:
"FastGPT Flow 的模块的输入和输出通过连接点进行连接,连接点的颜色代表了不同的数据类型。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.8060981035232544
,
"index"
:
16
},
{
"type"
:
"reRank"
,
"value"
:
0.9530133603823691
,
"index"
:
10
},
{
"type"
:
"rrf"
,
"value"
:
0.027071520029266508
,
"index"
:
13
}
]
},
{
"id"
:
"65a7be319d96e21823f69c98"
,
"q"
:
"FastGPT Flow 的工作流设计方案能够满足哪些问答场景?"
,
"a"
:
"FastGPT Flow 的工作流设计方案能够满足基本的 AI 知识库问答需求,并适应各种复杂的问答场景,例如联网搜索、数据库操作、数据实时更新、消息通知等。"
,
"chunkIndex"
:
0
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7be059d96e21823f69af5"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7be059d96e21823f69ae8"
,
"score"
:
[
{
"type"
:
"embedding"
,
"value"
:
0.814436137676239
,
"index"
:
8
},
{
"type"
:
"reRank"
,
"value"
:
0.8814109034236719
,
"index"
:
19
},
{
"type"
:
"rrf"
,
"value"
:
0.026992753623188405
,
"index"
:
16
}
]
},
{
"id"
:
"65a7e058fc13bdf20fd46577"
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"collectionId"
:
"65a7e01efc13bdf20fd45815"
,
"sourceName"
:
"FastGPT软著.pdf"
,
"sourceId"
:
"65a7e01dfc13bdf20fd457f3"
,
"q"
:
"FastGPT Flow 工作流设计112312 3123213123 232321312 21312 23一、介绍FastGPT 作为一款基于大型语言模型(LLM)的知识库问答系统,旨在为用户提供一个即插即用的解决方案。它集成了数据处理、模型调用等多项功能,通过引入 Flow 可视化工作流编排技术,进一步增强了对复杂问答场景的支持能力。本文将重点介绍 FastGPT Flow工作流的设计方案和应用优势。
\n
FastGPT Flow 工 作 流 采 用 了 React Flow 框 架 作 为 UI 底 座 , 结 合 自 研 的 FlowController 实现工作流的运行。FastGPT 使用 Flow 模块为用户呈现了一个直观、可视化的界面,从而简化了 AI 应用工作流程的设计和管理方式。React Flow 的应用使得用户能够以图形化的方式组织和编排工作流,这不仅使得工作流的创建过程更为直观,同时也为用户提供了强大且灵活的工作流编辑器。在 FastGPT Flow 工作流设计中,核心工作流模块包括用户引导、问题输入、知识库检索、AI 文本生成、问题分类、结构化内容提取、指定回复、应用调用和 HTTP 扩展,并允许用户在这类模块中进行自由组合和组装,从而衍生出一个新的模块。"
,
"a"
:
""
,
"chunkIndex"
:
0
,
"score"
:
[
{
"type"
:
"fullText"
,
"value"
:
1.0229779411764706
,
"index"
:
15
},
{
"type"
:
"reRank"
,
"value"
:
0.9577545043363116
,
"index"
:
8
},
{
"type"
:
"rrf"
,
"value"
:
0.026992753623188405
,
"index"
:
17
}
]
"collectionId"
:
"65abcfab9d1448617cba5f0d"
,
"results"
:
{
"insertLen"
:
5
,
//
分割成多少段
"overToken"
:
[],
"repeat"
:
[],
"error"
:
[]
}
],
"duration"
:
"2.978s"
,
"searchMode"
:
"mixedRecall"
,
"limit"
:
1500
,
"similarity"
:
0.1
,
"usingReRank"
:
true
,
"usingSimilarityFilter"
:
true
}
}
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
### 创建一个链接集合(商业版)
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
传入一个网络链接,创建一个集合,会先去对应网页抓取内容,再抓取的文字进行分割。
### Responses Data Schema
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
HTTP Status Code
**200**
```
bash
curl
--location
--request
POST
'http://localhost:3000/api/proApi/core/dataset/collection/create/link'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"link":"https://doc.fastgpt.in/docs/course/quick-start/",
"datasetId":"6593e137231a2be9c5603ba7",
"parentId": null,
|Name|Type|Required|Restrictions|Title|description|
|---|---|---|---|---|---|
|» code|integer|true|none||none|
|» statusText|string|true|none||none|
|» message|string|true|none||none|
|» data|object|true|none||none|
|»» list|
[
object
]
|true|none||none|
|»»» id|string|true|none||none|
|»»» q|string|true|none||none|
|»»» a|string|true|none||none|
|»»» chunkIndex|integer|true|none||none|
|»»» datasetId|string|true|none||none|
|»»» collectionId|string|true|none||none|
|»»» sourceName|string|true|none||none|
|»»» sourceId|string|true|none||none|
|»»» score|
[
object
]
|true|none||none|
|»»»» type|string|true|none||none|
|»»»» value|number|true|none||none|
|»»»» index|integer|true|none||none|
|»» duration|string|true|none||none|
|»» searchMode|string|true|none||none|
|»» limit|integer|true|none||none|
|»» similarity|number|true|none||none|
|»» usingReRank|boolean|true|none||none|
|»» usingSimilarityFilter|boolean|true|none||none|
"trainingType": "chunk",
"chunkSize":512,
"chunkSplitter":"",
"qaPrompt":"",
# openapi/知识库/知识库crud
"metadata":{
"webPageSelector":".docs-content"
}
}'
```
## GET 获取知识库列表
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
GET /core/dataset/list
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Params
{{% alert icon=" " context="success" %}}
-
link: 网络链接
-
datasetId: 知识库的ID(必填)
-
parentId: 父级ID,不填则默认为根目录
-
metadata.webPageSelector: 网页选择器,用于指定网页中的哪个元素作为文本(可选)
-
trainingType:(必填)
-
chunk: 按文本长度进行分割
-
qa: QA拆分
-
chunkSize: 每个 chunk 的长度(可选). chunk模式:100~3000; qa模式: 4000~模型最大token(16k模型通常建议不超过10000)
-
chunkSplitter: 自定义最高优先分割符号(可选)
-
qaPrompt: qa拆分自定义提示词(可选)
{{% /alert %}}
|Name|Location|Type|Required|Description|
|---|---|---|---|---|
|parentId|query|string| no |父级的ID|
|Authorization|header|string| no |none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
> Response Examples
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> 200 Response
data 为集合的 ID。
```
json
{}
{
"code"
:
200
,
"statusText"
:
""
,
"message"
:
""
,
"data"
:
{
"collectionId"
:
"65abd0ad9d1448617cba6031"
}
}
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### 创建一个文件集合(商业版)
### Responses Data Schema
传入一个文件,创建一个集合,会读取文件内容进行分割。目前支持:pdf, docx, md, txt, html, csv。
## GET 获取知识库详情
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
GET /core/dataset/detail
```
bash
curl
--location
--request
POST
'http://localhost:3000/api/proApi/core/dataset/collection/create/file'
\
--header
'Authorization: Bearer {{authorization}}'
\
--form
'file=@"C:\\Users\\user\\Desktop\\fastgpt测试文件\\index.html"'
\
--form
'data="{\"datasetId\":\"6593e137231a2be9c5603ba7\",\"parentId\":null,\"trainingType\":\"chunk\",\"chunkSize\":512,\"chunkSplitter\":\"\",\"qaPrompt\":\"\",\"metadata\":{}}"'
```
### Params
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|Name|Location|Type|Required|Description|
|---|---|---|---|---|
|id|query|string| no |知识库id|
|Authorization|header|string| no |none|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
> Response Examples
需要使用 POST form-data 的格式上传。包含 file 和 data 两个字段。
{{% alert icon=" " context="success" %}}
-
file: 文件
-
data: 知识库相关信息(json序列化后传入)
-
datasetId: 知识库的ID(必填)
-
parentId: 父级ID,不填则默认为根目录
-
trainingType:(必填)
-
chunk: 按文本长度进行分割
-
qa: QA拆分
-
chunkSize: 每个 chunk 的长度(可选). chunk模式:100~3000; qa模式: 4000~模型最大token(16k模型通常建议不超过10000)
-
chunkSplitter: 自定义最高优先分割符号(可选)
-
qaPrompt: qa拆分自定义提示词(可选)
{{% /alert %}}
> 200 Response
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
```
json
{}
```
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
# openapi/知识库/集合crud
## POST 获取知识库集合列表
POST /core/dataset/collection/list
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
data 为集合的 ID。
```
json
{
"pageNum"
:
1
,
"pageSize"
:
10
,
"datasetId"
:
"6597ca43e26f2a90a1501414"
,
"parentId"
:
null
,
"searchText"
:
""
,
"simple"
:
true
"code"
:
200
,
"statusText"
:
""
,
"message"
:
""
,
"data"
:
{
"collectionId"
:
"65abc044e4704bac793fbd81"
,
"results"
:
{
"insertLen"
:
1
,
"overToken"
:
[],
"repeat"
:
[],
"error"
:
[]
}
}
}
```
### Params
|Name|Location|Type|Required|Description|
|---|---|---|---|---|
|Authorization|header|string| no |none|
|body|body|object| no |none|
|» pageNum|body|integer| no |none|
|» pageSize|body|integer| no |none|
|» datasetId|body|string| yes |none|
|» parentId|body|null| no |none|
|» searchText|body|string| no |none|
|» simple|body|boolean| no |none|
> Response Examples
> 200 Response
```
json
{}
```
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
## GET 获取集合详情
GET /core/dataset/collection/detail
### Params
|Name|Location|Type|Required|Description|
|---|---|---|---|---|
|id|query|string| no |知识库id|
|Authorization|header|string| no |none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
> Response Examples
### 获取集合列表
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
POST
'http://localhost:3000/api/core/dataset/collection/list'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"pageNum":1,
"pageSize": 10,
"datasetId":"6593e137231a2be9c5603ba7",
"parentId": null,
"searchText":""
}'
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
pageNum: 页码(选填)
-
pageSize: 每页数量,最大30(选填)
-
datasetId: 知识库的ID(必填)
-
parentId: 父级Id(选填)
-
searchText: 模糊搜索文本(选填)
{{% /alert %}}
## PUT 更新集合
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
PUT /core/dataset/collection/update
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"id"
:
"6597ce094e10ee661f0891c8"
,
"parentId"
:
null
,
"name"
:
"222"
"code": 200,
"statusText": "",
"message": "",
"data": {
"pageNum": 1,
"pageSize": 10,
"data": [
{
"_id": "6593e137231a2be9c5603ba9",
"parentId": null,
"tmbId": "65422be6aa44b7da77729ec9",
"type": "virtual",
"name": "手动录入",
"updateTime": "2099-01-01T00:00:00.000Z",
"dataAmount": 3,
"trainingAmount": 0,
"canWrite": true
},
{
"_id": "65abd0ad9d1448617cba6031",
"parentId": null,
"tmbId": "65422be6aa44b7da77729ec9",
"type": "link",
"name": "快速上手 | FastGPT",
"rawLink": "https://doc.fastgpt.in/docs/course/quick-start/",
"updateTime": "2024-01-20T13:54:53.031Z",
"dataAmount": 3,
"trainingAmount": 0,
"canWrite": true
}
],
"total": 93
}
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» id|body|string| yes ||none|
|» parentId|body|null| no | 父级的id|none|
|» name|body|string| no | 名称|none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
> Response Examples
### 获取集合详情
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
GET
'http://localhost:3000/api/core/dataset/collection/detail?id=65abcfab9d1448617cba5f0d'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
id: 集合的ID
{{% /alert %}}
## POST 创建空集合(文件夹或者一个空集合)
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
POST /core/dataset/collection/create
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"datasetId"
:
"6597ca43e26f2a90a1501414"
,
"parentId"
:
null
,
"name"
:
"集合名"
,
"type"
:
"folder"
,
"metadata"
:
{}
"code": 200,
"statusText": "",
"message": "",
"data": {
"_id": "65abcfab9d1448617cba5f0d",
"parentId": null,
"teamId": "65422be6aa44b7da77729ec8",
"tmbId": "65422be6aa44b7da77729ec9",
"datasetId": {
"_id": "6593e137231a2be9c5603ba7",
"parentId": null,
"teamId": "65422be6aa44b7da77729ec8",
"tmbId": "65422be6aa44b7da77729ec9",
"type": "dataset",
"status": "active",
"avatar": "/icon/logo.svg",
"name": "FastGPT test",
"vectorModel": "text-embedding-ada-002",
"agentModel": "gpt-3.5-turbo-16k",
"intro": "",
"permission": "private",
"updateTime": "2024-01-02T10:11:03.084Z"
},
"type": "virtual",
"name": "测试训练",
"trainingType": "qa",
"chunkSize": 8000,
"chunkSplitter": "",
"qaPrompt": "11",
"rawTextLength": 40466,
"hashRawText": "47270840614c0cc122b29daaddc09c2a48f0ec6e77093611ab12b69cba7fee12",
"createTime": "2024-01-20T13:50:35.838Z",
"updateTime": "2024-01-20T13:50:35.838Z",
"canWrite": true,
"sourceName": "测试训练"
}
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» datasetId|body|string| yes ||none|
|» parentId|body|null| no ||none|
|» name|body|string| yes ||none|
|» type|body|
[
collection type
](
#schemacollection%20type
)
| yes ||none|
|» metadata|body|object| no ||none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
> Response Examples
### 修改集合信息
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
PUT
'http://localhost:3000/api/core/dataset/collection/update'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"id":"65abcfab9d1448617cba5f0d",
"parentId":null,
"name":"测2222试"
}'
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
id: 集合的ID
-
parentId: 修改父级ID(可选)
-
name: 修改集合名称(可选)
{{% /alert %}}
## POST 创建文本集合
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
POST /core/dataset/collection/create/text
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"text"
:
"xxxxxxxxxxxxxx"
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"parentId"
:
null
,
"name"
:
"测试"
,
"trainingType"
:
"qa"
,
"chunkSize"
:
8000
,
"chunkSplitter"
:
""
,
"qaPrompt"
:
""
,
"metadata"
:
{}
"code": 200,
"statusText": "",
"message": "",
"data": null
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» datasetId|body|string| no ||none|
|» parentId|body|null| no ||none|
|» name|body|string| yes ||none|
|» text|body|string| yes | 原文本|none|
|» trainingType|body|
[
training type
](
#schematraining%20type
)
| yes ||none|
|» chunkSize|body|integer| no | 分块大小|none|
|» chunkSplitter|body|string| no | 自定义最高优先级的分段符号|none|
|» qaPrompt|body|string| no ||none|
|» metadata|body|object| no ||none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
> Response Examples
### 删除一个集合
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
DELETE
'http://localhost:3000/api/core/dataset/collection/delete?id=65aa2a64e6cb9b8ccdc00de8'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
id: 集合的ID
{{% /alert %}}
## POST 创建网络链接集合
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
POST /core/dataset/collection/create/link
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"link"
:
"https://doc.fastgpt.in/docs/course/quick-start/"
,
"datasetId"
:
"6593e137231a2be9c5603ba7"
,
"parentId"
:
null
,
"trainingType"
:
"chunk"
,
"chunkSize"
:
512
,
"chunkSplitter"
:
""
,
"qaPrompt"
:
""
,
"metadata"
:
{
"webPageSelector"
:
".docs-content"
}
"code": 200,
"statusText": "",
"message": "",
"data": null
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» datasetId|body|string| yes ||none|
|» parentId|body|null| no ||none|
|» link|body|string| yes ||none|
|» trainingType|body|
[
training type
](
#schematraining%20type
)
| yes ||none|
|» chunkSize|body|integer| no ||none|
|» chunkSplitter|body|string| no ||none|
|» qaPrompt|body|string| no ||none|
|» metadata|body|object| no ||none|
|»» webPageSelector|body|string| no | web选择器|none|
> Response Examples
> 200 Response
```
json
{}
```
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
## DELETE 删除一个集合
DELETE /core/dataset/collection/delete
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
##
# Params
##
数据
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|id|query|string| no ||知识库id|
|Authorization|header|string| no ||none|
### 为集合批量添加添加数据
> Response Examples
注意,每次最多推送 200 组数据。
> 200 Response
{{
<
tabs
tabTotal=
"4"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
POST
'https://api.fastgpt.in/api/core/dataset/data/pushData'
\
--header
'Authorization: Bearer apikey'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"collectionId": "64663f451ba1676dbdef0499",
"trainingMode": "chunk",
"prompt": "可选。qa 拆分引导词,chunk 模式下忽略",
"billId": "可选。如果有这个值,本次的数据会被聚合到一个订单中,这个值可以重复使用。可以参考 [创建训练订单] 获取该值。",
"data": [
{
"q": "你是谁?",
"a": "我是FastGPT助手"
},
{
"q": "你会什么?",
"a": "我什么都会",
"indexes": [{
"defaultIndex": false,
"type":"custom",
"text":"自定义索引,不使用默认索引"
}]
}
]
}'
```
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
# openapi/知识库/数据crud
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
## POST 获取数据列表
{{% alert icon=" " context="success" %}}
-
collectionId: 集合ID(必填)
-
trainingType:(必填)
-
chunk: 按文本长度进行分割
-
qa: QA拆分
-
prompt: 自定义 QA 拆分提示词,需严格按照模板,建议不要传入。(选填)
-
data:(具体数据)
-
q: 主要数据(必填)
-
a: 辅助数据(选填)
-
indexes: 自定义索引(选填),不传入则默认使用q和a构建索引。也可以传入
{{% /alert %}}
POST /core/dataset/data/list
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
> Body Parameters
{{
<
tab
tabName=
"响应例子"
>
}}
{{
<
markdownify
>
}}
```
json
{
"pageNum"
:
1
,
"pageSize"
:
10
,
"collectionId"
:
"65a8d2700d70d3de0bf09186"
,
"searchText"
:
""
"code"
:
200
,
"statusText"
:
""
,
"data"
:
{
"insertLen"
:
1
,
//
最终插入成功的数量
"overToken"
:
[],
//
超出
token
的
"repeat"
:
[],
//
重复的数量
"error"
:
[]
//
其他错误
}
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» pageNum|body|integer| yes ||none|
|» pageSize|body|integer| yes ||none|
|» searchText|body|string| yes ||none|
|» collectionId|body|string| yes ||none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
> Response Examples
{{
<
tab
tabName=
"QA Prompt 模板"
>
}}
{{
<
markdownify
>
}}
> 200 Response
{{theme}} 里的内容可以换成数据的主题。默认为:它们可能包含多个主题内容
```
json
{}
```
我会给你一段文本,{{theme}},学习它们,并整理学习成果,要求为:
1. 提出最多 25 个问题。
2. 给出每个问题的答案。
3. 答案要详细完整,答案可以包含普通文字、链接、代码、表格、公示、媒体链接等 markdown 元素。
4. 按格式返回多个问题和答案:
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
## GET 获取数据详情
GET /core/dataset/data/detail
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|id|query|string| yes ||none|
|Authorization|header|string| no ||none|
> Response Examples
> 200 Response
Q1: 问题。
A1: 答案。
Q2:
A2:
……
```
json
{}
我的文本:"""{{text}}"""
```
### Responses
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
### Responses Data Schema
## DELETE 删除一条数据
DELETE /core/dataset/data/delete
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
### Params
{{
<
/
tabs
>
}}
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|id|query|string| no ||none|
|Authorization|header|string| no ||none|
> Response Examples
### 获取集合的数据列表
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
POST
'http://localhost:3000/api/core/dataset/data/list'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"pageNum":1,
"pageSize": 10,
"collectionId":"65abd4ac9d1448617cba6171",
"searchText":""
}'
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
pageNum: 页码(选填)
-
pageSize: 每页数量,最大30(选填)
-
collectionId: 集合的ID(必填)
-
searchText: 模糊搜索词(选填)
{{% /alert %}}
## PUT 更新数据
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
PUT /core/dataset/data/update
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"id"
:
"6597ce094e10ee661f0891c8"
,
"parentId"
:
null
,
"name"
:
"222"
"code": 200,
"statusText": "",
"message": "",
"data": {
"pageNum": 1,
"pageSize": 10,
"data": [
{
"_id": "65abd4b29d1448617cba61db",
"datasetId": "65abc9bd9d1448617cba5e6c",
"collectionId": "65abd4ac9d1448617cba6171",
"q": "N o . 2 0 2 2 1 2中 国 信 息 通 信 研 究 院京东探索研究院2022年 9月人工智能生成内容(AIGC)白皮书(2022 年)版权声明本白皮书版权属于中国信息通信研究院和京东探索研究院,并受法律保护。转载、摘编或利用其它方式使用本白皮书文字或者观点的,应注明“来源:中国信息通信研究院和京东探索研究院”。违反上述声明者,编者将追究其相关法律责任。前 言习近平总书记曾指出,“数字技术正以新理念、新业态、新模式全面融入人类经济、政治、文化、社会、生态文明建设各领域和全过程”。在当前数字世界和物理世界加速融合的大背景下,人工智能生成内容(Artificial Intelligence Generated Content,简称 AIGC)正在悄然引导着一场深刻的变革,重塑甚至颠覆数字内容的生产方式和消费模式,将极大地丰富人们的数字生活,是未来全面迈向数字文明新时代不可或缺的支撑力量。",
"a": "",
"chunkIndex": 0
},
{
"_id": "65abd4b39d1448617cba624d",
"datasetId": "65abc9bd9d1448617cba5e6c",
"collectionId": "65abd4ac9d1448617cba6171",
"q": "本白皮书重点从 AIGC 技术、应用和治理等维度进行了阐述。在技术层面,梳理提出了 AIGC 技术体系,既涵盖了对现实世界各种内容的数字化呈现和增强,也包括了基于人工智能的自主内容创作。在应用层面,重点分析了 AIGC 在传媒、电商、影视等行业和场景的应用情况,探讨了以虚拟数字人、写作机器人等为代表的新业态和新应用。在治理层面,从政策监管、技术能力、企业应用等视角,分析了AIGC 所暴露出的版权纠纷、虚假信息传播等各种问题。最后,从政府、行业、企业、社会等层面,给出了 AIGC 发展和治理建议。由于人工智能仍处于飞速发展阶段,我们对 AIGC 的认识还有待进一步深化,白皮书中存在不足之处,敬请大家批评指正。目 录一、 人工智能生成内容的发展历程与概念.............................................................. 1(一)AIGC 历史沿革 .......................................................................................... 1(二)AIGC 的概念与内涵 .................................................................................. 4二、人工智能生成内容的技术体系及其演进方向.................................................... 7(一)AIGC 技术升级步入深化阶段 .................................................................. 7(二)AIGC 大模型架构潜力凸显 .................................................................... 10(三)AIGC 技术演化出三大前沿能力 ............................................................ 18三、人工智能生成内容的应用场景.......................................................................... 26(一)AIGC+传媒:人机协同生产,",
"a": "",
"chunkIndex": 1
}
],
"total": 63
}
}
```
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» id|body|string| yes ||none|
|» q|body|string| yes ||none|
|» a|body|string| no ||none|
|» indexes|body|
[
[数据自定义向量
](
#schema%e6%95%b0%e6%8d%ae%e8%87%aa%e5%ae%9a%e4%b9%89%e5%90%91%e9%87%8f
)
]| no ||none|
> Response Examples
### 获取单条数据详情
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
GET
'http://localhost:3000/api/core/dataset/data/detail?id=65abd4b29d1448617cba61db'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
id: 数据的id
{{% /alert %}}
## POST 知识库插入记录(批量插入)
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
POST /core/dataset/data/pushData
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
> Body Parameters
```json
{
"collectionId"
:
"string"
,
"data"
:
[
{
"a"
:
"string"
,
"q"
:
"string"
,
"chunkIndex"
:
1
"code": 200,
"statusText": "",
"message": "",
"data": {
"id": "65abd4b29d1448617cba61db",
"q": "N o . 2 0 2 2 1 2中 国 信 息 通 信 研 究 院京东探索研究院2022年 9月人工智能生成内容(AIGC)白皮书(2022 年)版权声明本白皮书版权属于中国信息通信研究院和京东探索研究院,并受法律保护。转载、摘编或利用其它方式使用本白皮书文字或者观点的,应注明“来源:中国信息通信研究院和京东探索研究院”。违反上述声明者,编者将追究其相关法律责任。前 言习近平总书记曾指出,“数字技术正以新理念、新业态、新模式全面融入人类经济、政治、文化、社会、生态文明建设各领域和全过程”。在当前数字世界和物理世界加速融合的大背景下,人工智能生成内容(Artificial Intelligence Generated Content,简称 AIGC)正在悄然引导着一场深刻的变革,重塑甚至颠覆数字内容的生产方式和消费模式,将极大地丰富人们的数字生活,是未来全面迈向数字文明新时代不可或缺的支撑力量。",
"a": "",
"chunkIndex": 0,
"indexes": [
{
"defaultIndex": true,
"type": "chunk",
"dataId": "3720083",
"text": "N o . 2 0 2 2 1 2中 国 信 息 通 信 研 究 院京东探索研究院2022年 9月人工智能生成内容(AIGC)白皮书(2022 年)版权声明本白皮书版权属于中国信息通信研究院和京东探索研究院,并受法律保护。转载、摘编或利用其它方式使用本白皮书文字或者观点的,应注明“来源:中国信息通信研究院和京东探索研究院”。违反上述声明者,编者将追究其相关法律责任。前 言习近平总书记曾指出,“数字技术正以新理念、新业态、新模式全面融入人类经济、政治、文化、社会、生态文明建设各领域和全过程”。在当前数字世界和物理世界加速融合的大背景下,人工智能生成内容(Artificial Intelligence Generated Content,简称 AIGC)正在悄然引导着一场深刻的变革,重塑甚至颠覆数字内容的生产方式和消费模式,将极大地丰富人们的数字生活,是未来全面迈向数字文明新时代不可或缺的支撑力量。",
"_id": "65abd4b29d1448617cba61dc"
}
],
"datasetId": "65abc9bd9d1448617cba5e6c",
"collectionId": "65abd4ac9d1448617cba6171",
"sourceName": "中文-AIGC白皮书2022.pdf",
"sourceId": "65abd4ac9d1448617cba6166",
"isOwner": true,
"canWrite": true
}
],
"trainingMode"
:
"string"
,
"promot"
:
"string"
,
"billId"
:
""
}
```
### Params
|Name|Location|Type|Required|Title|Description|
|---|---|---|---|---|---|
|Authorization|header|string| no ||none|
|body|body|object| no ||none|
|» collectionId|body|string| yes ||none|
|» data|body|
[
object
]
| yes ||none|
|»» a|body|string| no ||none|
|»» q|body|string| no ||none|
|»» chunkIndex|body|integer| no ||none|
|» trainingMode|body|
[
training type
](
#schematraining%20type
)
| no ||none|
|» promot|body|string| no ||none|
|» billId|body|string| no ||none|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
> Response Examples
### 修改单条数据
> 200 Response
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
json
{}
```
bash
curl
--location
--request
PUT
'http://localhost:3000/api/core/dataset/data/update'
\
--header
'Authorization: Bearer {{authorization}}'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"id":"65abd4b29d1448617cba61db",
"q":"测试111",
"a":"sss",
"indexes":[]
}'
```
### Responses
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|HTTP Status Code |Meaning|Description|Data schema|
|---|---|---|---|
|200|
[
OK
](
https://tools.ietf.org/html/rfc7231#section-6.3.1
)
|成功|Inline|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
### Responses Data Schema
{{% alert icon=" " context="success" %}}
-
id: 数据的id
-
q: 主要数据(选填)
-
a: 辅助数据(选填)
-
indexes: 自定义索引(选填),类型参考
`为集合批量添加添加数据`
,建议直接不传。更新q,a后,如果有默认索引,则会直接更新默认索引。
{{% /alert %}}
# Data Schema
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
<h2
id=
"tocS_similary"
>
similary
</h2>
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
<a
id=
"schemasimilary"
></a>
<a
id=
"schema_similary"
></a>
<a
id=
"tocSsimilary"
></a>
<a
id=
"tocssimilary"
></a>
```json
1
{
"code": 200,
"statusText": "",
"message": "",
"data": null
}
```
### Attribute
|Name|Type|Required|Restrictions|Title|Description|
|---|---|---|---|---|---|
|
*anonymous*
|integer|false|none||none|
<h2
id=
"tocS_search mode"
>
search mode
</h2>
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
<a
id=
"schemasearch mode"
></a>
<a
id=
"schema_search mode"
></a>
<a
id=
"tocSsearch mode"
></a>
<a
id=
"tocssearch mode"
></a>
### 删除单条数据
```
json
"embedding"
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
DELETE
'http://localhost:3000/api/core/dataset/data/delete?id=65abd4b39d1448617cba624d'
\
--header
'Authorization: Bearer {{authorization}}'
\
```
### Attribute
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|Name|Type|Required|Restrictions|Title|Description|
|---|---|---|---|---|---|
|
*anonymous*
|string|false|none||none|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
#### Enum
{{% alert icon=" " context="success" %}}
-
id: 数据的id
{{% /alert %}}
|Name|Value|
|---|---|
|
*anonymous*
|embedding|
|
*anonymous*
|fullTextRecall|
|
*anonymous*
|mixedRecall|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
<h2
id=
"tocS_training type"
>
training type
</h2>
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
<a
id=
"schematraining type"
></a>
<a
id=
"schema_training type"
></a>
<a
id=
"tocStraining type"
></a>
<a
id=
"tocstraining type"
></a>
```json
"chunk"
{
"code": 200,
"statusText": "",
"message": "",
"data": "success"
}
```
### Attribute
|Name|Type|Required|Restrictions|Title|Description|
|---|---|---|---|---|---|
|
*anonymous*
|string|false|none||none|
#### Enum
|Name|Value|
|---|---|
|
*anonymous*
|chunk|
|
*anonymous*
|qa|
<h2
id=
"tocS_collection type"
>
collection type
</h2>
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
<a
id=
"schemacollection type"
></a>
<a
id=
"schema_collection type"
></a>
<a
id=
"tocScollection type"
></a>
<a
id=
"tocscollection type"
></a>
## 搜索测试
```
json
"folder"
{{
<
tabs
tabTotal=
"3"
>
}}
{{
<
tab
tabName=
"请求示例"
>
}}
{{
<
markdownify
>
}}
```
bash
curl
--location
--request
POST
'https://api.fastgpt.in/api/core/dataset/searchTest'
\
--header
'Authorization: Bearer fastgpt-xxxxx'
\
--header
'Content-Type: application/json'
\
--data-raw
'{
"datasetId": "知识库的ID",
"text": "导演是谁",
"limit": 5000,
"similarity": 0,
"searchMode": "embedding",
"usingReRank": false
}'
```
### Attribute
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
|Name|Type|Required|Restrictions|Title|Description|
|---|---|---|---|---|---|
|
*anonymous*
|string|false|none||none|
{{
<
tab
tabName=
"参数说明"
>
}}
{{
<
markdownify
>
}}
#### Enum
{{% alert icon=" " context="success" %}}
-
datasetId - 知识库ID
-
text - 需要测试的文本
-
limit - 最大 tokens 数量
-
similarity - 最低相关度(0~1,可选)
-
searchMode - 搜索模式:embedding | fullTextRecall | mixedRecall
-
usingReRank - 使用重排
{{% /alert %}}
|Name|Value|
|---|---|
|
*anonymous*
|folder|
|
*anonymous*
|virtual|
|
*anonymous*
|link|
|
*anonymous*
|file|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
<h2
id=
"tocS_数据自定义向量"
>
数据自定义向量
</h2>
{{
<
tab
tabName=
"响应示例"
>
}}
{{
<
markdownify
>
}}
<a
id=
"schema数据自定义向量"
></a>
<a
id=
"schema_数据自定义向量"
></a>
<a
id=
"tocS数据自定义向量"
></a>
<a
id=
"tocs数据自定义向量"
></a>
返回 top k 结果, limit 为最大 Tokens 数量,最多 20000 tokens。
```
json
{
"defaultIndex"
:
true
,
"type"
:
"string"
,
"text"
:
"string"
"code"
:
200
,
"statusText"
:
""
,
"data"
:
[
{
"id"
:
"65599c54a5c814fb803363cb"
,
"q"
:
"你是谁"
,
"a"
:
"我是FastGPT助手"
,
"datasetId"
:
"6554684f7f9ed18a39a4d15c"
,
"collectionId"
:
"6556cd795e4b663e770bb66d"
,
"sourceName"
:
"GBT 15104-2021 装饰单板贴面人造板.pdf"
,
"sourceId"
:
"6556cd775e4b663e770bb65c"
,
"score"
:
0.8050316572189331
},
......
]
}
```
### Attribute
|Name|Type|Required|Restrictions|Title|Description|
|---|---|---|---|---|---|
|defaultIndex|boolean|false|none||是否为默认|
|type|string|true|none||none|
|text|string|true|none||索引文本|
{{
<
/
markdownify
>
}}
{{
<
/
tab
>
}}
{{
<
/
tabs
>
}}
docSite/content/docs/development/upgrading/467.md
View file @
aab6ee51
...
...
@@ -27,7 +27,8 @@ curl --location --request POST 'https://{{host}}/api/admin/initv467' \
1.
修改了知识库UI及新的导入交互方式。
2.
优化知识库和对话的数据索引。
3.
知识库 openAPI,支持通过
API 操作知识库。(文档待补充)
3.
知识库 openAPI,支持通过
[
API 操作知识库
](
/docs/development/openapi/dataset
)
。
4.
新增 - 输入框变量提示。输入 { 号后将会获得可用变量提示。根据社区针对高级编排的反馈,我们计划于 2 月份的版本中,优化变量内容,支持模块的局部变量以及更多全局变量写入。
5.
修复 - API 对话时,chatId 冲突问题。
6.
修复 - Iframe 嵌入网页可能导致的 window.onLoad 冲突。
\ No newline at end of file
5.
优化 - 切换团队后会保存记录,下次登录时优先登录该团队。
6.
修复 - API 对话时,chatId 冲突问题。
7.
修复 - Iframe 嵌入网页可能导致的 window.onLoad 冲突。
\ No newline at end of file
packages/global/common/error/utils.ts
View file @
aab6ee51
import
{
replaceSensitiveLink
}
from
'../string/tools'
;
export
const
getErrText
=
(
err
:
any
,
def
=
''
)
=>
{
const
msg
:
string
=
typeof
err
===
'string'
?
err
:
err
?.
message
||
def
||
''
;
msg
&&
console
.
log
(
'error =>'
,
msg
);
return
msg
;
return
replaceSensitiveLink
(
msg
)
;
};
packages/global/common/string/tools.ts
View file @
aab6ee51
...
...
@@ -38,6 +38,12 @@ export function replaceVariable(text: string, obj: Record<string, string | numbe
return
text
||
''
;
}
/* replace sensitive link */
export
const
replaceSensitiveLink
=
(
text
:
string
)
=>
{
const
urlRegex
=
/
(?<
=https
?
:
\/\/)[^\s]
+/g
;
return
text
.
replace
(
urlRegex
,
'xxx'
);
};
export
const
getNanoid
=
(
size
=
12
)
=>
{
return
customAlphabet
(
'abcdefghijklmnopqrstuvwxyzABCDEFGHIJKLMNOPQRSTUVWXYZ1234567890'
,
size
)();
};
packages/service/common/file/utils.ts
View file @
aab6ee51
...
...
@@ -4,7 +4,7 @@ export const removeFilesByPaths = (paths: string[]) => {
paths
.
forEach
((
path
)
=>
{
fs
.
unlink
(
path
,
(
err
)
=>
{
if
(
err
)
{
console
.
error
(
err
);
//
console.error(err);
}
});
});
...
...
packages/service/common/response/index.ts
View file @
aab6ee51
...
...
@@ -3,6 +3,7 @@ import { sseResponseEventEnum } from './constant';
import
{
proxyError
,
ERROR_RESPONSE
,
ERROR_ENUM
}
from
'@fastgpt/global/common/error/errorCode'
;
import
{
addLog
}
from
'../system/log'
;
import
{
clearCookie
}
from
'../../support/permission/controller'
;
import
{
replaceSensitiveLink
}
from
'@fastgpt/global/common/string/tools'
;
export
interface
ResponseType
<
T
=
any
>
{
code
:
number
;
...
...
@@ -52,7 +53,7 @@ export const jsonRes = <T = any>(
res
.
status
(
code
).
json
({
code
,
statusText
:
''
,
message
:
message
||
msg
,
message
:
replaceSensitiveLink
(
message
||
msg
)
,
data
:
data
!==
undefined
?
data
:
null
});
};
...
...
@@ -90,7 +91,7 @@ export const sseErrRes = (res: NextApiResponse, error: any) => {
responseWrite({
res,
event: sseResponseEventEnum.error,
data: JSON.stringify({ message:
msg
})
data: JSON.stringify({ message:
replaceSensitiveLink(msg)
})
});
};
...
...
packages/service/support/permission/controller.ts
View file @
aab6ee51
...
...
@@ -168,6 +168,10 @@ export async function parseHeaderCert({
return
Promise
.
reject
(
ERROR_ENUM
.
unAuthorization
);
})();
if
(
!
authRoot
&&
(
!
teamId
||
!
tmbId
))
{
return
Promise
.
reject
(
ERROR_ENUM
.
unAuthorization
);
}
return
{
userId
:
String
(
uid
),
teamId
:
String
(
teamId
),
...
...
packages/web/components/common/Icon/icons/support/account/loginoutLight.svg
View file @
aab6ee51
<?xml version="1.0" standalone="no"?><!DOCTYPE svg PUBLIC "-//W3C//DTD SVG 1.1//EN" "http://www.w3.org/Graphics/SVG/1.1/DTD/svg11.dtd">
<svg
t=
"1689855121257"
class=
"icon"
viewBox=
"0 0 1024 1024"
version=
"1.1"
xmlns=
"http://www.w3.org/2000/svg"
p-id=
"3135"
xmlns:xlink=
"http://www.w3.org/1999/xlink"
width=
"64"
height=
"64"
><path
d=
"M952.7 492.1c-1.4-1.8-3.1-3.4-4.8-4.9l-179-178.9c-12.5-12.5-32.9-12.5-45.4 0s-12.5 32.9 0 45.4l126 126H421.3h-0.1c-18.2 0-32.9 14.8-32.9 33s14.7 33 32.9 33c0.3 0.1 0.5 0 0.7 0h427.8l-126 126c-12.3 12.3-12.3 32.4 0 44.7l0.7 0.7c12.3 12.3 32.4 12.3 44.7 0l182-182c11.7-11.7 12.3-30.6 1.6-43z"
fill=
"#515151"
p-id=
"3136"
></path><path
d=
"M562.3 799c-18 0-32.7 14.7-32.7 32.7v63.8H129.2V128.7h400.4v63.1c0 18 14.7 32.7 32.7 32.7s32.7-14.7 32.7-32.7V96.3c0-3.5-0.6-6.8-1.6-10-4.2-13.3-16.6-23-31.2-23H96.6c-18 0-32.7 14.7-32.7 32.7v831.9c0 14.2 9.2 26.3 21.8 30.8 3.6 1.4 7.5 2.1 11.5 2.1h463.2c0.6 0 1.3 0.1 1.9 0.1 18 0 32.7-14.7 32.7-32.7v-96.5c0-18-14.7-32.7-32.7-32.7z"
fill=
"#515151"
p-id=
"3137"
></path><path
d=
"M256.8 512.7a32.9 33 0 1 0 65.8 0 32.9 33 0 1 0-65.8 0Z"
fill=
"#515151"
p-id=
"3138"
></path></svg>
\ No newline at end of file
<?xml version="1.0" standalone="no"?>
<!DOCTYPE svg PUBLIC "-//W3C//DTD SVG 1.1//EN" "http://www.w3.org/Graphics/SVG/1.1/DTD/svg11.dtd">
<svg
t=
"1689855121257"
class=
"icon"
viewBox=
"0 0 1024 1024"
version=
"1.1"
xmlns=
"http://www.w3.org/2000/svg"
p-id=
"3135"
xmlns:xlink=
"http://www.w3.org/1999/xlink"
width=
"64"
height=
"64"
>
<path
d=
"M952.7 492.1c-1.4-1.8-3.1-3.4-4.8-4.9l-179-178.9c-12.5-12.5-32.9-12.5-45.4 0s-12.5 32.9 0 45.4l126 126H421.3h-0.1c-18.2 0-32.9 14.8-32.9 33s14.7 33 32.9 33c0.3 0.1 0.5 0 0.7 0h427.8l-126 126c-12.3 12.3-12.3 32.4 0 44.7l0.7 0.7c12.3 12.3 32.4 12.3 44.7 0l182-182c11.7-11.7 12.3-30.6 1.6-43z"
p-id=
"3136"
></path>
<path
d=
"M562.3 799c-18 0-32.7 14.7-32.7 32.7v63.8H129.2V128.7h400.4v63.1c0 18 14.7 32.7 32.7 32.7s32.7-14.7 32.7-32.7V96.3c0-3.5-0.6-6.8-1.6-10-4.2-13.3-16.6-23-31.2-23H96.6c-18 0-32.7 14.7-32.7 32.7v831.9c0 14.2 9.2 26.3 21.8 30.8 3.6 1.4 7.5 2.1 11.5 2.1h463.2c0.6 0 1.3 0.1 1.9 0.1 18 0 32.7-14.7 32.7-32.7v-96.5c0-18-14.7-32.7-32.7-32.7z"
p-id=
"3137"
></path>
<path
d=
"M256.8 512.7a32.9 33 0 1 0 65.8 0 32.9 33 0 1 0-65.8 0Z"
p-id=
"3138"
></path>
</svg>
\ No newline at end of file
projects/app/public/docs/versionIntro.md
View file @
aab6ee51
...
...
@@ -4,8 +4,9 @@
2.
优化知识库和对话的数据索引,加快数据操作。
3.
知识库 openAPI,支持通过 API 操作知识库。
4.
新增 - 输入框变量提示。输入 { 号后将会获得可用变量提示。根据社区针对高级编排的反馈,我们计划于 2 月份的版本中,优化变量内容,支持模块的局部变量以及更多全局变量写入。
5.
修复 - API 对话时,chatId 冲突问题。
6.
修复 - Iframe 嵌入网页可能导致的 window.onLoad 冲突。
7.
[
使用文档
](
https://doc.fastgpt.in/docs/intro/
)
8.
[
点击查看高级编排介绍文档
](
https://doc.fastgpt.in/docs/workflow
)
9.
[
点击查看商业版
](
https://doc.fastgpt.in/docs/commercial/
)
5.
优化 - 切换团队后会保存记录,下次登录时优先登录该团队。
6.
修复 - API 对话时,chatId 冲突问题。
7.
修复 - Iframe 嵌入网页可能导致的 window.onLoad 冲突。
8.
[
使用文档
](
https://doc.fastgpt.in/docs/intro/
)
9.
[
点击查看高级编排介绍文档
](
https://doc.fastgpt.in/docs/workflow
)
10.
[
点击查看商业版
](
https://doc.fastgpt.in/docs/commercial/
)
projects/app/public/locales/zh/common.json
View file @
aab6ee51
...
...
@@ -95,7 +95,7 @@
"Last Step"
:
"上一步"
,
"Last use time"
:
"最后使用时间"
,
"Load Failed"
:
"加载失败"
,
"Loading"
:
"加载中"
,
"Loading"
:
"加载中
...
"
,
"Max credit"
:
"最大金额"
,
"Max credit tips"
:
"该链接最大可消耗多少金额,超出后链接将被禁止使用。-1 代表无限制。"
,
"More settings"
:
"更多设置"
,
...
...
@@ -541,7 +541,8 @@
"success"
:
"开始同步"
}
},
"training"
:
{}
"training"
:
{
}
},
"data"
:
{
"Auxiliary Data"
:
"辅助数据"
,
...
...
projects/app/src/components/ChatBox/MessageInput.tsx
View file @
aab6ee51
import
{
useSpeech
}
from
'@/web/common/hooks/useSpeech'
;
import
{
useSystemStore
}
from
'@/web/common/system/useSystemStore'
;
import
{
Box
,
Flex
,
Image
,
Spinner
,
Textarea
}
from
'@chakra-ui/react'
;
import
React
,
{
useRef
,
useEffect
,
useCallback
,
useState
}
from
'react'
;
import
React
,
{
useRef
,
useEffect
,
useCallback
,
useState
,
useTransition
}
from
'react'
;
import
{
useTranslation
}
from
'next-i18next'
;
import
MyTooltip
from
'../MyTooltip'
;
import
MyIcon
from
'@fastgpt/web/components/common/Icon'
;
...
...
@@ -37,7 +37,7 @@ const MessageInput = ({
showFileSelector
=
false
,
resetInputVal
}:
{
onChange
:
(
e
:
string
)
=>
void
;
onChange
?
:
(
e
:
string
)
=>
void
;
onSendMessage
:
(
e
:
string
)
=>
void
;
onStop
:
()
=>
void
;
isChatting
:
boolean
;
...
...
@@ -45,6 +45,8 @@ const MessageInput = ({
TextareaDom
:
React
.
MutableRefObject
<
HTMLTextAreaElement
|
null
>
;
resetInputVal
:
(
val
:
string
)
=>
void
;
})
=>
{
const
[,
startSts
]
=
useTransition
();
const
{
shareId
}
=
useRouter
().
query
as
{
shareId
?:
string
};
const
{
isSpeaking
,
...
...
@@ -330,17 +332,29 @@ ${images.map((img) => JSON.stringify({ src: img.src })).join('\n')}
const
textarea
=
e
.
target
;
textarea
.
style
.
height
=
textareaMinH
;
textarea
.
style
.
height
=
`${textarea.scrollHeight}px`
;
onChange
(
textarea
.
value
);
startSts
(()
=>
{
onChange
?.(
textarea
.
value
);
});
}
}
onKeyDown=
{
(
e
)
=>
{
// enter send.(pc or iframe && enter and unPress shift)
if
((
isPc
||
window
!==
parent
)
&&
e
.
keyCode
===
13
&&
!
e
.
shiftKey
)
{
handleSend
();
e
.
preventDefault
();
const
isEnter
=
e
.
keyCode
===
13
;
if
(
isEnter
&&
TextareaDom
.
current
&&
(
e
.
ctrlKey
||
e
.
altKey
))
{
TextareaDom
.
current
.
value
+=
'\n'
;
TextareaDom
.
current
.
style
.
height
=
textareaMinH
;
TextareaDom
.
current
.
style
.
height
=
`${TextareaDom.current.scrollHeight}px`
;
return
;
}
// 全选内容
// @ts-ignore
e
.
key
===
'a'
&&
e
.
ctrlKey
&&
e
.
target
?.
select
();
if
((
isPc
||
window
!==
parent
)
&&
e
.
keyCode
===
13
&&
!
e
.
shiftKey
)
{
handleSend
();
e
.
preventDefault
();
}
}
}
onPaste=
{
(
e
)
=>
{
const
clipboardData
=
e
.
clipboardData
;
...
...
projects/app/src/components/ChatBox/index.tsx
View file @
aab6ee51
...
...
@@ -36,7 +36,7 @@ import { adaptChat2GptMessages } from '@fastgpt/global/core/chat/adapt';
import
{
useMarkdown
}
from
'@/web/common/hooks/useMarkdown'
;
import
{
ModuleItemType
}
from
'@fastgpt/global/core/module/type.d'
;
import
{
VariableInputEnum
}
from
'@fastgpt/global/core/module/constants'
;
import
{
useForm
}
from
'react-hook-form'
;
import
{
UseFormReturn
,
useForm
}
from
'react-hook-form'
;
import
type
{
ChatMessageItemType
}
from
'@fastgpt/global/core/ai/type.d'
;
import
{
fileDownload
}
from
'@/web/common/file/utils'
;
import
{
htmlTemplate
}
from
'@/constants/common'
;
...
...
@@ -65,7 +65,7 @@ const SelectMarkCollection = dynamic(() => import('./SelectMarkCollection'));
import
styles
from
'./index.module.scss'
;
import
{
postQuestionGuide
}
from
'@/web/core/ai/api'
;
import
{
splitGuideModule
}
from
'@fastgpt/global/core/module/utils'
;
import
type
{
AppTTSConfigType
}
from
'@fastgpt/global/core/module/type.d'
;
import
type
{
AppTTSConfigType
,
VariableItemType
}
from
'@fastgpt/global/core/module/type.d'
;
import
MessageInput
from
'./MessageInput'
;
import
{
ModuleOutputKeyEnum
}
from
'@fastgpt/global/core/module/constants'
;
import
ChatBoxDivider
from
'../core/chat/Divider'
;
...
...
@@ -98,6 +98,15 @@ enum FeedbackTypeEnum {
hidden
=
'hidden'
}
const
MessageCardStyle
:
BoxProps
=
{
px
:
4
,
py
:
3
,
borderRadius
:
'0 8px 8px 8px'
,
boxShadow
:
'0 0 8px rgba(0,0,0,0.15)'
,
display
:
'inline-block'
,
maxW
:
[
'calc(100% - 25px)'
,
'calc(100% - 40px)'
]
};
type
Props
=
{
feedbackType
?:
`
${
FeedbackTypeEnum
}
`
;
showMarkIcon
?:
boolean
;
// admin mark dataset
...
...
@@ -157,7 +166,6 @@ const ChatBox = (
const
isNewChatReplace
=
useRef
(
false
);
const
[
refresh
,
setRefresh
]
=
useState
(
false
);
const
[
variables
,
setVariables
]
=
useState
<
Record
<
string
,
any
>>
({});
// settings variable
const
[
chatHistory
,
setChatHistory
]
=
useState
<
ChatSiteItemType
[]
>
([]);
const
[
feedbackId
,
setFeedbackId
]
=
useState
<
string
>
();
const
[
readFeedbackData
,
setReadFeedbackData
]
=
useState
<
{
...
...
@@ -180,7 +188,17 @@ const ChatBox = (
);
// compute variable input is finish.
const
[
variableInputFinish
,
setVariableInputFinish
]
=
useState
(
false
);
const
chatForm
=
useForm
<
{
variables
:
Record
<
string
,
any
>
;
}
>
({
defaultValues
:
{
variables
:
{}
}
});
const
{
setValue
,
watch
,
handleSubmit
}
=
chatForm
;
const
variables
=
watch
(
'variables'
);
const
[
variableInputFinish
,
setVariableInputFinish
]
=
useState
(
false
);
// clicked start chat button
const
variableIsFinish
=
useMemo
(()
=>
{
if
(
!
variableModules
||
variableModules
.
length
===
0
||
chatHistory
.
length
>
0
)
return
true
;
...
...
@@ -194,21 +212,15 @@ const ChatBox = (
return
variableInputFinish
;
},
[
chatHistory
.
length
,
variableInputFinish
,
variableModules
,
variables
]);
const
{
register
,
reset
,
getValues
,
setValue
,
handleSubmit
}
=
useForm
<
Record
<
string
,
any
>>
({
defaultValues
:
variables
});
// 滚动到底部
const
scrollToBottom
=
useCallback
(
(
behavior
:
'smooth'
|
'auto'
=
'smooth'
)
=>
{
if
(
!
ChatBoxRef
.
current
)
return
;
ChatBoxRef
.
current
.
scrollTo
({
top
:
ChatBoxRef
.
current
.
scrollHeight
,
behavior
});
},
[
ChatBoxRef
]
);
const
scrollToBottom
=
(
behavior
:
'smooth'
|
'auto'
=
'smooth'
)
=>
{
if
(
!
ChatBoxRef
.
current
)
return
;
ChatBoxRef
.
current
.
scrollTo
({
top
:
ChatBoxRef
.
current
.
scrollHeight
,
behavior
});
};
// 聊天信息生成中……获取当前滚动条位置,判断是否需要滚动到底部
const
generatingScroll
=
useCallback
(
throttle
(()
=>
{
...
...
@@ -222,28 +234,31 @@ const ChatBox = (
[]
);
// eslint-disable-next-line react-hooks/exhaustive-deps
const
generatingMessage
=
({
text
=
''
,
status
,
name
}:
generatingMessageProps
)
=>
{
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
...(
text
?
{
value
:
item
.
value
+
text
}
:
{}),
...(
status
&&
name
?
{
status
,
moduleName
:
name
}
:
{})
};
})
);
generatingScroll
();
};
const
generatingMessage
=
useCallback
(
({
text
=
''
,
status
,
name
}:
generatingMessageProps
)
=>
{
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
...(
text
?
{
value
:
item
.
value
+
text
}
:
{}),
...(
status
&&
name
?
{
status
,
moduleName
:
name
}
:
{})
};
})
);
generatingScroll
();
},
[
generatingScroll
]
);
// 重置输入内容
const
resetInputVal
=
useCallback
((
val
:
string
)
=>
{
...
...
@@ -284,149 +299,157 @@ const ChatBox = (
}
}
catch
(
error
)
{}
},
[
questionGuide
,
s
crollToBottom
,
s
hareId
]
[
questionGuide
,
shareId
]
);
/**
* user confirm send prompt
*/
const
sendPrompt
=
useCallback
(
async
(
variables
:
Record
<
string
,
any
>
=
{},
inputVal
=
''
,
history
=
chatHistory
)
=>
{
if
(
!
onStartChat
)
return
;
if
(
isChatting
)
{
toast
({
title
:
'正在聊天中...请等待结束'
,
status
:
'warning'
});
return
;
}
questionGuideController
.
current
?.
abort
(
'stop'
);
// get input value
const
val
=
inputVal
.
trim
();
if
(
!
val
)
{
toast
({
title
:
'内容为空'
,
status
:
'warning'
});
return
;
}
const
newChatList
:
ChatSiteItemType
[]
=
[
...
history
,
{
dataId
:
nanoid
(),
obj
:
'Human'
,
value
:
val
,
status
:
'finish'
},
{
dataId
:
nanoid
(),
obj
:
'AI'
,
value
:
''
,
status
:
'loading'
({
inputVal
=
''
,
history
=
chatHistory
}:
{
inputVal
?:
string
;
history
?:
ChatSiteItemType
[];
})
=>
{
handleSubmit
(
async
({
variables
})
=>
{
if
(
!
onStartChat
)
return
;
if
(
isChatting
)
{
toast
({
title
:
'正在聊天中...请等待结束'
,
status
:
'warning'
});
return
;
}
questionGuideController
.
current
?.
abort
(
'stop'
);
// get input value
const
val
=
inputVal
.
trim
();
if
(
!
val
)
{
toast
({
title
:
'内容为空'
,
status
:
'warning'
});
return
;
}
];
// 插入内容
setChatHistory
(
newChatList
);
// 清空输入内容
resetInputVal
(
''
);
setQuestionGuide
([]);
setTimeout
(()
=>
{
scrollToBottom
();
},
100
);
try
{
// create abort obj
const
abortSignal
=
new
AbortController
();
chatController
.
current
=
abortSignal
;
const
messages
=
adaptChat2GptMessages
({
messages
:
newChatList
,
reserveId
:
true
});
const
{
responseData
,
responseText
,
isNewChat
=
false
}
=
await
onStartChat
({
chatList
:
newChatList
.
map
((
item
)
=>
({
dataId
:
item
.
dataId
,
obj
:
item
.
obj
,
value
:
item
.
value
,
status
:
item
.
status
,
moduleName
:
item
.
moduleName
})),
messages
,
controller
:
abortSignal
,
generatingMessage
,
variables
});
const
newChatList
:
ChatSiteItemType
[]
=
[
...
history
,
{
dataId
:
nanoid
(),
obj
:
'Human'
,
value
:
val
,
status
:
'finish'
},
{
dataId
:
nanoid
(),
obj
:
'AI'
,
value
:
''
,
status
:
'loading'
}
];
isNewChatReplace
.
current
=
isNewChat
;
// set finish status
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
status
:
'finish'
,
responseData
};
})
);
// 插入内容
setChatHistory
(
newChatList
);
// 清空输入内容
resetInputVal
(
''
);
setQuestionGuide
([]);
setTimeout
(()
=>
{
createQuestionGuide
({
history
:
newChatList
.
map
((
item
,
i
)
=>
i
===
newChatList
.
length
-
1
?
{
...
item
,
value
:
responseText
}
:
item
)
});
generatingScroll
();
isPc
&&
TextareaDom
.
current
?.
focus
();
scrollToBottom
();
},
100
);
}
catch
(
err
:
any
)
{
toast
({
title
:
t
(
getErrText
(
err
,
'core.chat.error.Chat error'
)),
status
:
'error'
,
duration
:
5000
,
isClosable
:
true
});
try
{
// create abort obj
const
abortSignal
=
new
AbortController
();
chatController
.
current
=
abortSignal
;
const
messages
=
adaptChat2GptMessages
({
messages
:
newChatList
,
reserveId
:
true
});
const
{
responseData
,
responseText
,
isNewChat
=
false
}
=
await
onStartChat
({
chatList
:
newChatList
.
map
((
item
)
=>
({
dataId
:
item
.
dataId
,
obj
:
item
.
obj
,
value
:
item
.
value
,
status
:
item
.
status
,
moduleName
:
item
.
moduleName
})),
messages
,
controller
:
abortSignal
,
generatingMessage
,
variables
});
if
(
!
err
?.
responseText
)
{
resetInputVal
(
inputVal
);
setChatHistory
(
newChatList
.
slice
(
0
,
newChatList
.
length
-
2
));
}
isNewChatReplace
.
current
=
isNewChat
;
// set finish status
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
status
:
'finish'
};
})
);
}
// set finish status
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
status
:
'finish'
,
responseData
};
})
);
setTimeout
(()
=>
{
createQuestionGuide
({
history
:
newChatList
.
map
((
item
,
i
)
=>
i
===
newChatList
.
length
-
1
?
{
...
item
,
value
:
responseText
}
:
item
)
});
generatingScroll
();
isPc
&&
TextareaDom
.
current
?.
focus
();
},
100
);
}
catch
(
err
:
any
)
{
toast
({
title
:
t
(
getErrText
(
err
,
'core.chat.error.Chat error'
)),
status
:
'error'
,
duration
:
5000
,
isClosable
:
true
});
if
(
!
err
?.
responseText
)
{
resetInputVal
(
inputVal
);
setChatHistory
(
newChatList
.
slice
(
0
,
newChatList
.
length
-
2
));
}
// set finish status
setChatHistory
((
state
)
=>
state
.
map
((
item
,
index
)
=>
{
if
(
index
!==
state
.
length
-
1
)
return
item
;
return
{
...
item
,
status
:
'finish'
};
})
);
}
})();
},
[
chatHistory
,
onStartChat
,
isChatting
,
resetInputVal
,
toast
,
scrollToBottom
,
generatingMessage
,
createQuestionGuide
,
generatingMessage
,
generatingScroll
,
handleSubmit
,
isChatting
,
isPc
,
t
onStartChat
,
resetInputVal
,
t
,
toast
]
);
...
...
@@ -444,11 +467,14 @@ const ChatBox = (
);
setChatHistory
((
state
)
=>
(
index
===
0
?
[]
:
state
.
slice
(
0
,
index
)));
sendPrompt
(
variables
,
delHistory
[
0
].
value
,
chatHistory
.
slice
(
0
,
index
));
sendPrompt
({
inputVal
:
delHistory
[
0
].
value
,
history
:
chatHistory
.
slice
(
0
,
index
)
});
}
catch
(
error
)
{}
setLoading
(
false
);
},
[
chatHistory
,
onDelMessage
,
sendPrompt
,
setLoading
,
variables
]
[
chatHistory
,
onDelMessage
,
sendPrompt
,
setLoading
]
);
// delete one message
const
delOneMessage
=
useCallback
(
...
...
@@ -471,27 +497,21 @@ const ChatBox = (
defaultVal
[
item
.
key
]
=
''
;
});
reset
(
e
||
defaultVal
);
setVariables
(
e
||
defaultVal
);
setValue
(
'variables'
,
e
||
defaultVal
);
},
resetHistory
(
e
)
{
setVariableInputFinish
(
!!
e
.
length
);
setChatHistory
(
e
);
},
scrollToBottom
,
sendPrompt
:
(
question
:
string
)
=>
handleSubmit
((
item
)
=>
sendPrompt
(
item
,
question
))()
sendPrompt
:
(
question
:
string
)
=>
{
sendPrompt
({
inputVal
:
question
});
}
}));
/* style start */
const
MessageCardStyle
:
BoxProps
=
{
px
:
4
,
py
:
3
,
borderRadius
:
'0 8px 8px 8px'
,
boxShadow
:
'0 0 8px rgba(0,0,0,0.15)'
,
display
:
'inline-block'
,
maxW
:
[
'calc(100% - 25px)'
,
'calc(100% - 40px)'
]
};
const
showEmpty
=
useMemo
(
()
=>
feConfigs
?.
show_emptyChat
&&
...
...
@@ -534,14 +554,18 @@ const ChatBox = (
useEffect
(()
=>
{
const
windowMessage
=
({
data
}:
MessageEvent
<
{
type
:
'sendPrompt'
;
text
:
string
}
>
)
=>
{
if
(
data
?.
type
===
'sendPrompt'
&&
data
?.
text
)
{
handleSubmit
((
item
)
=>
sendPrompt
(
item
,
data
.
text
))();
sendPrompt
({
inputVal
:
data
.
text
});
}
};
window
.
addEventListener
(
'message'
,
windowMessage
);
eventBus
.
on
(
EventNameEnum
.
sendQuestion
,
({
text
}:
{
text
:
string
})
=>
{
if
(
!
text
)
return
;
handleSubmit
((
data
)
=>
sendPrompt
(
data
,
text
))();
sendPrompt
({
inputVal
:
text
});
});
eventBus
.
on
(
EventNameEnum
.
editQuestion
,
({
text
}:
{
text
:
string
})
=>
{
if
(
!
text
)
return
;
...
...
@@ -553,140 +577,81 @@ const ChatBox = (
eventBus
.
off
(
EventNameEnum
.
sendQuestion
);
eventBus
.
off
(
EventNameEnum
.
editQuestion
);
};
},
[
handleSubmit
,
resetInputVal
,
sendPrompt
]);
},
[
resetInputVal
,
sendPrompt
]);
const
onSubmitVariables
=
useCallback
(
(
data
:
Record
<
string
,
any
>
)
=>
{
setVariableInputFinish
(
true
);
onUpdateVariable
?.(
data
);
},
[
onUpdateVariable
]
);
const
HumanChatCard
=
useCallback
(
({
item
,
index
}:
{
item
:
ChatSiteItemType
;
index
:
number
})
=>
{
return
(
<>
{
/* control icon */
}
<
Flex
w=
{
'100%'
}
alignItems=
{
'center'
}
justifyContent=
{
'flex-end'
}
>
<
ChatControllerComponent
chat=
{
item
}
onDelete=
{
onDelMessage
?
()
=>
{
delOneMessage
({
dataId
:
item
.
dataId
,
index
});
}
:
undefined
}
onRetry=
{
useCallback
(()
=>
retryInput
(
index
),
[
index
])
}
/>
<
ChatAvatar
src=
{
userAvatar
}
type=
{
'Human'
}
/>
</
Flex
>
{
/* content */
}
<
Box
mt=
{
[
'6px'
,
2
]
}
textAlign=
{
'right'
}
>
<
Card
className=
"markdown"
{
...
MessageCardStyle
}
bg=
{
'primary.200'
}
borderRadius=
{
'8px 0 8px 8px'
}
textAlign=
{
'left'
}
>
<
Markdown
source=
{
item
.
value
}
isChatting=
{
false
}
/>
</
Card
>
</
Box
>
</>
);
},
[]
);
return
(
<
Flex
flexDirection=
{
'column'
}
h=
{
'100%'
}
>
<
Script
src=
"/js/html2pdf.bundle.min.js"
strategy=
"lazyOnload"
></
Script
>
{
/* chat box container */
}
<
Box
ref=
{
ChatBoxRef
}
flex=
{
'1 0 0'
}
h=
{
0
}
w=
{
'100%'
}
overflow=
{
'overlay'
}
px=
{
[
4
,
0
]
}
pb=
{
3
}
>
<
Box
id=
"chat-container"
maxW=
{
[
'100%'
,
'92%'
]
}
h=
{
'100%'
}
mx=
{
'auto'
}
>
{
showEmpty
&&
<
Empty
/>
}
{
!!
welcomeText
&&
(
<
Box
py=
{
3
}
>
{
/* avatar */
}
<
ChatAvatar
src=
{
appAvatar
}
type=
{
'AI'
}
/>
{
/* message */
}
<
Box
textAlign=
{
'left'
}
>
<
Card
order=
{
2
}
mt=
{
2
}
{
...
MessageCardStyle
}
bg=
{
'white'
}
>
<
Markdown
source=
{
`~~~guide \n${welcomeText}`
}
isChatting=
{
false
}
/>
</
Card
>
</
Box
>
</
Box
>
)
}
{
!!
welcomeText
&&
<
WelcomeText
appAvatar=
{
appAvatar
}
welcomeText=
{
welcomeText
}
/>
}
{
/* variable input */
}
{
!!
variableModules
?.
length
&&
(
<
Box
py=
{
3
}
>
{
/* avatar */
}
<
ChatAvatar
src=
{
appAvatar
}
type=
{
'AI'
}
/>
{
/* message */
}
<
Box
textAlign=
{
'left'
}
>
<
Card
order=
{
2
}
mt=
{
2
}
bg=
{
'white'
}
w=
{
'400px'
}
{
...
MessageCardStyle
}
>
{
variableModules
.
map
((
item
)
=>
(
<
Box
key=
{
item
.
id
}
mb=
{
4
}
>
<
VariableLabel
required=
{
item
.
required
}
>
{
item
.
label
}
</
VariableLabel
>
{
item
.
type
===
VariableInputEnum
.
input
&&
(
<
Input
isDisabled=
{
variableIsFinish
}
bg=
{
'myWhite.400'
}
{
...
register
(
item
.
key
,
{
required
:
item
.
required
})}
/>
)
}
{
item
.
type
===
VariableInputEnum
.
textarea
&&
(
<
Textarea
isDisabled=
{
variableIsFinish
}
bg=
{
'myWhite.400'
}
{
...
register
(
item
.
key
,
{
required
:
item
.
required
})}
rows=
{
5
}
maxLength=
{
4000
}
/>
)
}
{
item
.
type
===
VariableInputEnum
.
select
&&
(
<
MySelect
width=
{
'100%'
}
isDisabled=
{
variableIsFinish
}
list=
{
(
item
.
enums
||
[]).
map
((
item
)
=>
({
label
:
item
.
value
,
value
:
item
.
value
}))
}
{
...
register
(
item
.
key
,
{
required
:
item
.
required
})}
value=
{
getValues
(
item
.
key
)
}
onchange=
{
(
e
)
=>
{
setValue
(
item
.
key
,
e
);
setRefresh
(
!
refresh
);
}
}
/>
)
}
</
Box
>
))
}
{
!
variableIsFinish
&&
(
<
Button
leftIcon=
{
<
MyIcon
name=
{
'core/chat/chatFill'
}
w=
{
'16px'
}
/>
}
size=
{
'sm'
}
maxW=
{
'100px'
}
onClick=
{
handleSubmit
((
data
)
=>
{
onUpdateVariable
?.(
data
);
setVariables
(
data
);
setVariableInputFinish
(
true
);
})
}
>
{
t
(
'core.chat.Start Chat'
)
}
</
Button
>
)
}
</
Card
>
</
Box
>
</
Box
>
<
VariableInput
appAvatar=
{
appAvatar
}
variableModules=
{
variableModules
}
variableIsFinish=
{
variableIsFinish
}
chatForm=
{
chatForm
}
onSubmitVariables=
{
onSubmitVariables
}
/>
)
}
{
/* chat history */
}
<
Box
id=
{
'history'
}
>
{
chatHistory
.
map
((
item
,
index
)
=>
(
<
Box
key=
{
item
.
dataId
}
py=
{
5
}
>
{
item
.
obj
===
'Human'
&&
(
<>
{
/* control icon */
}
<
Flex
w=
{
'100%'
}
alignItems=
{
'center'
}
justifyContent=
{
'flex-end'
}
>
<
ChatController
chat=
{
item
}
onDelete=
{
onDelMessage
?
()
=>
{
delOneMessage
({
dataId
:
item
.
dataId
,
index
});
}
:
undefined
}
onRetry=
{
()
=>
retryInput
(
index
)
}
/>
<
ChatAvatar
src=
{
userAvatar
}
type=
{
'Human'
}
/>
</
Flex
>
{
/* content */
}
<
Box
mt=
{
[
'6px'
,
2
]
}
textAlign=
{
'right'
}
>
<
Card
className=
"markdown"
{
...
MessageCardStyle
}
bg=
{
'primary.200'
}
borderRadius=
{
'8px 0 8px 8px'
}
textAlign=
{
'left'
}
>
<
Markdown
source=
{
item
.
value
}
isChatting=
{
false
}
/>
</
Card
>
</
Box
>
</>
)
}
{
item
.
obj
===
'Human'
&&
<
HumanChatCard
item=
{
item
}
index=
{
index
}
/>
}
{
item
.
obj
===
'AI'
&&
(
<>
{
/* control icon */
}
<
Flex
w=
{
'100%'
}
alignItems=
{
'center'
}
>
<
ChatAvatar
src=
{
appAvatar
}
type=
{
'AI'
}
/>
<
ChatController
{
/* control icon */
}
<
ChatControllerComponent
ml=
{
2
}
chat=
{
item
}
setChatHistory=
{
setChatHistory
}
...
...
@@ -723,36 +688,35 @@ const ChatBox = (
}
:
undefined
}
onAddUserLike=
{
(()
=>
{
if
(
feedbackType
!==
FeedbackTypeEnum
.
user
||
item
.
userBadFeedback
)
{
return
;
}
return
()
=>
{
if
(
!
item
.
dataId
||
!
chatId
||
!
appId
)
return
;
const
isGoodFeedback
=
!!
item
.
userGoodFeedback
;
setChatHistory
((
state
)
=>
state
.
map
((
chatItem
)
=>
chatItem
.
dataId
===
item
.
dataId
?
{
...
chatItem
,
userGoodFeedback
:
isGoodFeedback
?
undefined
:
'yes'
}
:
chatItem
)
);
try
{
updateChatUserFeedback
({
appId
,
chatId
,
chatItemId
:
item
.
dataId
,
shareId
,
outLinkUid
,
userGoodFeedback
:
isGoodFeedback
?
undefined
:
'yes'
});
}
catch
(
error
)
{}
};
})()
}
onAddUserLike=
{
feedbackType
!==
FeedbackTypeEnum
.
user
||
item
.
userBadFeedback
?
undefined
:
()
=>
{
if
(
!
item
.
dataId
||
!
chatId
||
!
appId
)
return
;
const
isGoodFeedback
=
!!
item
.
userGoodFeedback
;
setChatHistory
((
state
)
=>
state
.
map
((
chatItem
)
=>
chatItem
.
dataId
===
item
.
dataId
?
{
...
chatItem
,
userGoodFeedback
:
isGoodFeedback
?
undefined
:
'yes'
}
:
chatItem
)
);
try
{
updateChatUserFeedback
({
appId
,
chatId
,
chatItemId
:
item
.
dataId
,
shareId
,
outLinkUid
,
userGoodFeedback
:
isGoodFeedback
?
undefined
:
'yes'
});
}
catch
(
error
)
{}
}
}
onCloseUserLike=
{
feedbackType
===
FeedbackTypeEnum
.
admin
?
()
=>
{
...
...
@@ -931,13 +895,12 @@ const ChatBox = (
</
Box
>
</
Box
>
{
/* message input */
}
{
onStartChat
&&
variableIsFinish
&&
active
?
(
{
onStartChat
&&
variableIsFinish
&&
active
&&
(
<
MessageInput
onChange=
{
(
e
)
=>
{
setRefresh
(
!
refresh
);
}
}
onSendMessage=
{
(
e
)
=>
{
handleSubmit
((
data
)
=>
sendPrompt
(
data
,
e
))();
onSendMessage=
{
(
inputVal
)
=>
{
sendPrompt
({
inputVal
});
}
}
onStop=
{
()
=>
chatController
.
current
?.
abort
(
'stop'
)
}
isChatting=
{
isChatting
}
...
...
@@ -945,7 +908,7 @@ const ChatBox = (
resetInputVal=
{
resetInputVal
}
showFileSelector=
{
showFileSelector
}
/>
)
:
null
}
)
}
{
/* user feedback modal */
}
{
!!
feedbackId
&&
chatId
&&
appId
&&
(
<
FeedbackModal
...
...
@@ -1115,30 +1078,125 @@ export const useChatBox = () => {
};
};
function VariableLabel
({
required = false
,
children
const WelcomeText = React.memo(function Welcome
({
appAvatar
,
welcomeText
}: {
required?: boolean
;
children: React.ReactNode |
string;
appAvatar?: string
;
welcomeText:
string;
}) {
return (
<Box as={'label'} display={'inline-block'} position={'relative'} mb={1}>
{children}
{required && (
<Box
position={'absolute'}
top={'-2px'}
right={'-10px'}
color={'red.500'}
fontWeight={'bold'}
>
*
</Box>
)}
<Box py={3}>
{/* avatar */}
<ChatAvatar src={appAvatar} type={'AI'} />
{/* message */}
<Box textAlign={'left'}>
<Card order={2} mt={2} {...MessageCardStyle} bg={'white'}>
<Markdown source={`~~~guide \n${welcomeText}`} isChatting={false} />
</Card>
</Box>
</Box>
);
}
});
const VariableInput = React.memo(function VariableInput({
appAvatar,
variableModules,
variableIsFinish,
chatForm,
onSubmitVariables
}: {
appAvatar?: string;
variableModules: VariableItemType[];
variableIsFinish: boolean;
onSubmitVariables: (e: Record<string, any>) => void;
chatForm: UseFormReturn<{
variables: Record<string, any>;
}>;
}) {
const { t } = useTranslation();
const { register, setValue, handleSubmit: handleSubmitChat, watch } = chatForm;
const variables = watch('variables');
return (
<Box py={3}>
{/* avatar */}
<ChatAvatar src={appAvatar} type={'AI'} />
{/* message */}
<Box textAlign={'left'}>
<Card order={2} mt={2} bg={'white'} w={'400px'} {...MessageCardStyle}>
{variableModules.map((item) => (
<Box key={item.id} mb={4}>
<Box as={'label'} display={'inline-block'} position={'relative'} mb={1}>
{item.label}
{item.required && (
<Box
position={'absolute'}
top={'-2px'}
right={'-10px'}
color={'red.500'}
fontWeight={'bold'}
>
*
</Box>
)}
</Box>
{item.type === VariableInputEnum.input && (
<Input
isDisabled={variableIsFinish}
bg={'myWhite.400'}
{...register(`variables.${item.key}`, {
required: item.required
})}
/>
)}
{item.type === VariableInputEnum.textarea && (
<Textarea
isDisabled={variableIsFinish}
bg={'myWhite.400'}
{...register(`variables.${item.key}`, {
required: item.required
})}
rows={5}
maxLength={4000}
/>
)}
{item.type === VariableInputEnum.select && (
<MySelect
width={'100%'}
isDisabled={variableIsFinish}
list={(item.enums || []).map((item) => ({
label: item.value,
value: item.value
}))}
{...register(`variables.${item.key}`, {
required: item.required
})}
value={variables[item.key]}
onchange={(e) => {
setValue(`variables.${item.key}`, e);
}}
/>
)}
</Box>
))}
{!variableIsFinish && (
<Button
leftIcon={<MyIcon name={'core/chat/chatFill'} w={'16px'} />}
size={'sm'}
maxW={'100px'}
onClick={handleSubmitChat((data) => {
onSubmitVariables(data);
})}
>
{t('core.chat.Start Chat')}
</Button>
)}
</Card>
</Box>
</Box>
);
});
function ChatAvatar({ src, type }: { src?: string; type: 'Human' | 'AI' }) {
const theme = useTheme();
return (
...
...
@@ -1173,7 +1231,7 @@ function Empty() {
);
}
function ChatController
({
const ChatControllerComponent = React.memo(function ChatControllerComponent
({
chat,
setChatHistory,
display,
...
...
@@ -1226,7 +1284,7 @@ function ChatController({
return (
<Flex {...controlContainerStyle} ml={ml} mr={mr} display={display}>
<MyTooltip label={
'复制'
}>
<MyTooltip label={
t('common.Copy')
}>
<MyIcon
{...controlIconStyle}
name={'copy'}
...
...
@@ -1246,7 +1304,7 @@ function ChatController({
/>
</MyTooltip>
)}
<MyTooltip label={
'删除'
}>
<MyTooltip label={
t('common.Delete')
}>
<MyIcon
{...controlIconStyle}
name={'delete'}
...
...
@@ -1259,7 +1317,7 @@ function ChatController({
{showVoiceIcon &&
hasAudio &&
(audioLoading ? (
<MyTooltip label={
'加载中...'
}>
<MyTooltip label={
t('common.Loading')
}>
<MyIcon {...controlIconStyle} name={'common/loading'} />
</MyTooltip>
) : audioPlaying ? (
...
...
@@ -1372,4 +1430,4 @@ function ChatController({
)}
</Flex>
);
}
}
);
projects/app/src/components/Markdown/index.tsx
View file @
aab6ee51
...
...
@@ -35,36 +35,79 @@ export enum CodeClassName {
img
=
'img'
}
function
Code
({
inline
,
className
,
children
}:
any
)
{
const
match
=
/language-
(\w
+
)
/
.
exec
(
className
||
''
);
const
codeType
=
match
?.[
1
];
const
Markdown
=
({
source
,
isChatting
=
false
}:
{
source
:
string
;
isChatting
?:
boolean
})
=>
{
const
components
=
useMemo
<
any
>
(
()
=>
({
img
:
Image
,
pre
:
'div'
,
p
:
(
pProps
:
any
)
=>
<
p
{
...
pProps
}
dir=
"auto"
/>,
code
:
Code
,
a
:
A
}),
[]
);
if
(
codeType
===
CodeClassName
.
mermaid
)
{
return
<
MermaidCodeBlock
code=
{
String
(
children
)
}
/>;
}
const
formatSource
=
source
.
replace
(
/
\\
n/g
,
'\n '
)
.
replace
(
/
(
http
[
s
]?
:
\/\/[^\s
,。
]
+
)([
。,
])
/g
,
'$1 $2'
)
.
replace
(
/
\n
*
(\[
QUOTE SIGN
\]\(
.*
\))
/g
,
'$1'
);
if
(
codeType
===
CodeClassName
.
guide
)
{
return
<
ChatGuide
text=
{
String
(
children
)
}
/>;
}
if
(
codeType
===
CodeClassName
.
questionGuide
)
{
return
<
QuestionGuide
text=
{
String
(
children
)
}
/>;
}
if
(
codeType
===
CodeClassName
.
echarts
)
{
return
<
EChartsCodeBlock
code=
{
String
(
children
)
}
/>;
}
if
(
codeType
===
CodeClassName
.
img
)
{
return
<
ImageBlock
images=
{
String
(
children
)
}
/>;
}
return
(
<
CodeLight
className=
{
className
}
inline=
{
inline
}
match=
{
match
}
>
{
children
}
</
CodeLight
>
<
ReactMarkdown
className=
{
`markdown ${styles.markdown}
${isChatting ? `
$
{
formatSource
?
styles
.
waitingAnimation
:
styles
.
animation
}
` : ''}
`
}
remarkPlugins=
{
[
RemarkMath
,
RemarkGfm
,
RemarkBreaks
]
}
rehypePlugins=
{
[
RehypeKatex
]
}
components=
{
components
}
linkTarget=
{
'_blank'
}
>
{
formatSource
}
</
ReactMarkdown
>
);
}
function
Image
({
src
}:
{
src
?:
string
})
{
};
export
default
React
.
memo
(
Markdown
);
const
Code
=
React
.
memo
(
function
Code
(
e
:
any
)
{
const
{
inline
,
className
,
children
}
=
e
;
const
match
=
/language-
(\w
+
)
/
.
exec
(
className
||
''
);
const
codeType
=
match
?.[
1
];
const
strChildren
=
String
(
children
);
const
Component
=
useMemo
(()
=>
{
if
(
codeType
===
CodeClassName
.
mermaid
)
{
return
<
MermaidCodeBlock
code=
{
strChildren
}
/>;
}
if
(
codeType
===
CodeClassName
.
guide
)
{
return
<
ChatGuide
text=
{
strChildren
}
/>;
}
if
(
codeType
===
CodeClassName
.
questionGuide
)
{
return
<
QuestionGuide
text=
{
strChildren
}
/>;
}
if
(
codeType
===
CodeClassName
.
echarts
)
{
return
<
EChartsCodeBlock
code=
{
strChildren
}
/>;
}
if
(
codeType
===
CodeClassName
.
img
)
{
return
<
ImageBlock
images=
{
strChildren
}
/>;
}
return
(
<
CodeLight
className=
{
className
}
inline=
{
inline
}
match=
{
match
}
>
{
children
}
</
CodeLight
>
);
},
[
codeType
,
className
,
inline
,
match
,
strChildren
]);
return
Component
;
});
const
Image
=
React
.
memo
(
function
Image
({
src
}:
{
src
?:
string
})
{
return
<
MdImage
src=
{
src
}
/>;
}
function
A
({
children
,
...
props
}:
any
)
{
}
);
const
A
=
React
.
memo
(
function
A
({
children
,
...
props
}:
any
)
{
const
{
t
}
=
useTranslation
();
// empty href link
...
...
@@ -109,38 +152,4 @@ function A({ children, ...props }: any) {
}
return
<
Link
{
...
props
}
>
{
children
}
</
Link
>;
}
const
Markdown
=
({
source
,
isChatting
=
false
}:
{
source
:
string
;
isChatting
?:
boolean
})
=>
{
const
components
=
useMemo
<
any
>
(
()
=>
({
img
:
Image
,
pre
:
'div'
,
p
:
(
pProps
:
any
)
=>
<
p
{
...
pProps
}
dir=
"auto"
/>,
code
:
Code
,
a
:
A
}),
[]
);
const
formatSource
=
source
.
replace
(
/
\\
n/g
,
'\n '
)
.
replace
(
/
(
http
[
s
]?
:
\/\/[^\s
,。
]
+
)([
。,
])
/g
,
'$1 $2'
)
.
replace
(
/
\n
*
(\[
QUOTE SIGN
\]\(
.*
\))
/g
,
'$1'
);
return
(
<
ReactMarkdown
className=
{
`markdown ${styles.markdown}
${isChatting ? `
$
{
formatSource
?
styles
.
waitingAnimation
:
styles
.
animation
}
` : ''}
`
}
remarkPlugins=
{
[
RemarkMath
,
RemarkGfm
,
RemarkBreaks
]
}
rehypePlugins=
{
[
RehypeKatex
]
}
components=
{
components
}
linkTarget=
{
'_blank'
}
>
{
formatSource
}
</
ReactMarkdown
>
);
};
export
default
React
.
memo
(
Markdown
);
});
projects/app/src/components/common/Textarea/TagTextarea.tsx
View file @
aab6ee51
...
...
@@ -79,6 +79,8 @@ const TagTextarea = ({ defaultValues, onUpdate, ...props }: Props) => {
ref=
{
InputRef
}
variant=
{
'unstyled'
}
display=
{
'inline-block'
}
h=
{
'24px'
}
borderRadius=
{
'none'
}
w=
"auto"
onBlur=
{
(
e
)
=>
{
const
value
=
e
.
target
.
value
;
...
...
projects/app/src/components/core/module/AIChatSettingsModal.tsx
View file @
aab6ee51
...
...
@@ -66,7 +66,6 @@ const AIChatSettingsModal = ({
},
[
getValues
]);
const
quoteTemplateVariables
=
(()
=>
[
...
pickerMenu
,
{
key
:
'q'
,
label
:
'q'
,
...
...
@@ -91,15 +90,21 @@ const AIChatSettingsModal = ({
key
:
'index'
,
label
:
t
(
'core.dataset.search.Quote index'
),
icon
:
'core/app/simpleMode/variable'
}
},
...
pickerMenu
])();
const
quotePromptVariables
=
(()
=>
[
...
pickerMenu
,
{
key
:
'quote'
,
label
:
t
(
'core.app.Quote templates'
),
icon
:
'core/app/simpleMode/variable'
}
},
{
key
:
'question'
,
label
:
t
(
'core.module.input.label.user question'
),
icon
:
'core/app/simpleMode/variable'
},
...
pickerMenu
])();
const
LabelStyles
:
BoxProps
=
{
...
...
projects/app/src/components/support/user/team/TeamManageModal/InviteModal.tsx
View file @
aab6ee51
...
...
@@ -55,11 +55,13 @@ const InviteModal = ({
openConfirm
(
()
=>
onClose
(),
undefined
,
t
(
'user.team.Invite Member Success Tip'
,
{
success
:
res
.
invite
.
length
,
inValid
:
res
.
inValid
.
map
((
item
)
=>
item
.
username
).
join
(
', '
),
inTeam
:
res
.
inTeam
.
map
((
item
)
=>
item
.
username
).
join
(
', '
)
})
<
Box
whiteSpace=
{
'pre-wrap'
}
>
{
t
(
'user.team.Invite Member Success Tip'
,
{
success
:
res
.
invite
.
length
,
inValid
:
res
.
inValid
.
map
((
item
)
=>
item
.
username
).
join
(
', '
),
inTeam
:
res
.
inTeam
.
map
((
item
)
=>
item
.
username
).
join
(
', '
)
})
}
</
Box
>
)();
},
errorToast
:
t
(
'user.team.Invite Member Failed Tip'
)
...
...
projects/app/src/components/support/user/team/TeamManageModal/index.tsx
View file @
aab6ee51
...
...
@@ -75,7 +75,7 @@ const TeamManageModal = ({ onClose }: { onClose: () => void }) => {
const
{
mutate
:
onSwitchTeam
,
isLoading
:
isSwitchTeam
}
=
useRequest
({
mutationFn
:
async
(
teamId
:
string
)
=>
{
const
token
=
await
putSwitchTeam
(
teamId
);
setToken
(
token
);
token
&&
setToken
(
token
);
return
initUserInfo
();
},
errorToast
:
t
(
'user.team.Switch Team Failed'
)
...
...
@@ -286,13 +286,7 @@ const TeamManageModal = ({ onClose }: { onClose: () => void }) => {
size=
"sm"
borderRadius=
{
'md'
}
ml=
{
3
}
leftIcon=
{
<
MyIcon
name=
{
'support/account/loginoutLight'
}
w=
{
'14px'
}
color=
{
'primary.500'
}
/>
}
leftIcon=
{
<
MyIcon
name=
{
'support/account/loginoutLight'
}
w=
{
'14px'
}
/>
}
onClick=
{
()
=>
{
openLeaveConfirm
(()
=>
onLeaveTeam
(
userInfo
?.
team
?.
teamId
))();
}
}
...
...
projects/app/src/pages/account/components/Info.tsx
View file @
aab6ee51
...
...
@@ -271,28 +271,32 @@ const UserInfo = () => {
)
}
</
Flex
>
</
Box
>
<
Box
mt=
{
6
}
whiteSpace=
{
'nowrap'
}
w=
{
[
'85%'
,
'300px'
]
}
>
<
Flex
alignItems=
{
'center'
}
>
<
Box
flex=
{
'1 0 0'
}
fontSize=
{
'md'
}
>
{
t
(
'support.user.team.Dataset usage'
)
}
:
{
datasetUsageMap
.
usedSize
}
/
{
datasetSub
.
maxSize
}
{
feConfigs
?.
show_pay
&&
(
<
Box
mt=
{
6
}
whiteSpace=
{
'nowrap'
}
w=
{
[
'85%'
,
'300px'
]
}
>
<
Flex
alignItems=
{
'center'
}
>
<
Box
flex=
{
'1 0 0'
}
fontSize=
{
'md'
}
>
{
t
(
'support.user.team.Dataset usage'
)
}
:
{
datasetUsageMap
.
usedSize
}
/
{
datasetSub
.
maxSize
}
</
Box
>
{
userInfo
?.
team
?.
canWrite
&&
(
<
Button
size=
{
'sm'
}
onClick=
{
onOpenSubDatasetModal
}
>
{
t
(
'support.wallet.Buy more'
)
}
</
Button
>
)
}
</
Flex
>
<
Box
mt=
{
1
}
>
<
Progress
value=
{
datasetUsageMap
.
value
}
colorScheme=
{
datasetUsageMap
.
colorScheme
}
borderRadius=
{
'md'
}
isAnimated
hasStripe
borderWidth=
{
'1px'
}
borderColor=
{
'borderColor.base'
}
/>
</
Box
>
<
Button
size=
{
'sm'
}
onClick=
{
onOpenSubDatasetModal
}
>
{
t
(
'support.wallet.Buy more'
)
}
</
Button
>
</
Flex
>
<
Box
mt=
{
1
}
>
<
Progress
value=
{
datasetUsageMap
.
value
}
colorScheme=
{
datasetUsageMap
.
colorScheme
}
borderRadius=
{
'md'
}
isAnimated
hasStripe
borderWidth=
{
'1px'
}
borderColor=
{
'borderColor.base'
}
/>
</
Box
>
</
Box
>
)
}
</>
)
}
...
...
projects/app/src/pages/api/core/dataset/collection/create/file.ts
deleted
100644 → 0
View file @
91b7d81c
import
type
{
NextApiRequest
,
NextApiResponse
}
from
'next'
;
import
{
jsonRes
}
from
'@fastgpt/service/common/response'
;
import
{
connectToDatabase
}
from
'@/service/mongo'
;
import
{
uploadFile
}
from
'@fastgpt/service/common/file/gridfs/controller'
;
import
{
getUploadModel
}
from
'@fastgpt/service/common/file/multer'
;
import
{
authDataset
}
from
'@fastgpt/service/support/permission/auth/dataset'
;
import
{
FileCreateDatasetCollectionParams
}
from
'@fastgpt/global/core/dataset/api'
;
import
{
removeFilesByPaths
}
from
'@fastgpt/service/common/file/utils'
;
import
{
createOneCollection
}
from
'@fastgpt/service/core/dataset/collection/controller'
;
import
{
DatasetCollectionTypeEnum
}
from
'@fastgpt/global/core/dataset/constants'
;
/**
* Creates the multer uploader
*/
const
upload
=
getUploadModel
({
maxSize
:
500
*
1024
*
1024
});
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
<
any
>
)
{
let
filePaths
:
string
[]
=
[];
const
{
datasetId
}
=
req
.
query
as
{
datasetId
:
string
};
try
{
await
connectToDatabase
();
const
{
teamId
,
tmbId
}
=
await
authDataset
({
req
,
authToken
:
true
,
authApiKey
:
true
,
per
:
'w'
,
datasetId
});
const
{
file
,
bucketName
,
data
}
=
await
upload
.
doUpload
<
FileCreateDatasetCollectionParams
>
(
req
,
res
);
filePaths
=
[
file
.
path
];
if
(
!
file
||
!
bucketName
)
{
throw
new
Error
(
'file is empty'
);
}
const
{
fileMetadata
,
collectionMetadata
,
...
collectionData
}
=
data
;
// upload file and create collection
const
fileId
=
await
uploadFile
({
teamId
,
tmbId
,
bucketName
,
path
:
file
.
path
,
filename
:
file
.
originalname
,
contentType
:
file
.
mimetype
,
metadata
:
fileMetadata
});
// create collection
const
collectionId
=
await
createOneCollection
({
...
collectionData
,
metadata
:
collectionMetadata
,
teamId
,
tmbId
,
type
:
DatasetCollectionTypeEnum
.
file
,
fileId
});
jsonRes
(
res
,
{
data
:
collectionId
});
}
catch
(
error
)
{
jsonRes
(
res
,
{
code
:
500
,
error
});
}
removeFilesByPaths
(
filePaths
);
}
export
const
config
=
{
api
:
{
bodyParser
:
false
}
};
projects/app/src/pages/api/core/dataset/collection/create/link.ts
deleted
100644 → 0
View file @
91b7d81c
/*
Create one dataset collection
*/
import
type
{
NextApiRequest
,
NextApiResponse
}
from
'next'
;
import
{
jsonRes
}
from
'@fastgpt/service/common/response'
;
import
{
connectToDatabase
}
from
'@/service/mongo'
;
import
type
{
LinkCreateDatasetCollectionParams
}
from
'@fastgpt/global/core/dataset/api.d'
;
import
{
authDataset
}
from
'@fastgpt/service/support/permission/auth/dataset'
;
import
{
createOneCollection
}
from
'@fastgpt/service/core/dataset/collection/controller'
;
import
{
TrainingModeEnum
,
DatasetCollectionTypeEnum
}
from
'@fastgpt/global/core/dataset/constants'
;
import
{
checkDatasetLimit
}
from
'@fastgpt/service/support/permission/limit/dataset'
;
import
{
predictDataLimitLength
}
from
'@fastgpt/global/core/dataset/utils'
;
import
{
createTrainingBill
}
from
'@fastgpt/service/support/wallet/bill/controller'
;
import
{
BillSourceEnum
}
from
'@fastgpt/global/support/wallet/bill/constants'
;
import
{
getQAModel
,
getVectorModel
}
from
'@/service/core/ai/model'
;
import
{
reloadCollectionChunks
}
from
'@fastgpt/service/core/dataset/collection/utils'
;
import
{
startQueue
}
from
'@/service/utils/tools'
;
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
<
any
>
)
{
try
{
await
connectToDatabase
();
const
{
link
,
trainingType
=
TrainingModeEnum
.
chunk
,
chunkSize
=
512
,
chunkSplitter
,
qaPrompt
,
...
body
}
=
req
.
body
as
LinkCreateDatasetCollectionParams
;
const
{
teamId
,
tmbId
,
dataset
}
=
await
authDataset
({
req
,
authToken
:
true
,
authApiKey
:
true
,
datasetId
:
body
.
datasetId
,
per
:
'w'
});
// 1. check dataset limit
await
checkDatasetLimit
({
teamId
,
freeSize
:
global
.
feConfigs
?.
subscription
?.
datasetStoreFreeSize
,
insertLen
:
predictDataLimitLength
(
trainingType
,
new
Array
(
10
))
});
// 2. create collection
const
collectionId
=
await
createOneCollection
({
...
body
,
name
:
link
,
teamId
,
tmbId
,
type
:
DatasetCollectionTypeEnum
.
link
,
trainingType
,
chunkSize
,
chunkSplitter
,
qaPrompt
,
rawLink
:
link
});
// 3. create bill and start sync
const
{
billId
}
=
await
createTrainingBill
({
teamId
,
tmbId
,
appName
:
'core.dataset.collection.Sync Collection'
,
billSource
:
BillSourceEnum
.
training
,
vectorModel
:
getVectorModel
(
dataset
.
vectorModel
).
name
,
agentModel
:
getQAModel
(
dataset
.
agentModel
).
name
});
await
reloadCollectionChunks
({
collectionId
,
tmbId
,
billId
});
startQueue
();
jsonRes
(
res
,
{
data
:
{
collectionId
}
});
}
catch
(
err
)
{
jsonRes
(
res
,
{
code
:
500
,
error
:
err
});
}
}
projects/app/src/pages/api/core/dataset/collection/create/text.ts
deleted
100644 → 0
View file @
91b7d81c
/*
Create one dataset collection
*/
import
type
{
NextApiRequest
,
NextApiResponse
}
from
'next'
;
import
{
jsonRes
}
from
'@fastgpt/service/common/response'
;
import
{
connectToDatabase
}
from
'@/service/mongo'
;
import
type
{
TextCreateDatasetCollectionParams
}
from
'@fastgpt/global/core/dataset/api.d'
;
import
{
authDataset
}
from
'@fastgpt/service/support/permission/auth/dataset'
;
import
{
createOneCollection
}
from
'@fastgpt/service/core/dataset/collection/controller'
;
import
{
TrainingModeEnum
,
DatasetCollectionTypeEnum
}
from
'@fastgpt/global/core/dataset/constants'
;
import
{
splitText2Chunks
}
from
'@fastgpt/global/common/string/textSplitter'
;
import
{
checkDatasetLimit
}
from
'@fastgpt/service/support/permission/limit/dataset'
;
import
{
predictDataLimitLength
}
from
'@fastgpt/global/core/dataset/utils'
;
import
{
pushDataToTrainingQueue
}
from
'@/service/core/dataset/data/controller'
;
import
{
hashStr
}
from
'@fastgpt/global/common/string/tools'
;
import
{
createTrainingBill
}
from
'@fastgpt/service/support/wallet/bill/controller'
;
import
{
BillSourceEnum
}
from
'@fastgpt/global/support/wallet/bill/constants'
;
import
{
getQAModel
,
getVectorModel
}
from
'@/service/core/ai/model'
;
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
<
any
>
)
{
try
{
await
connectToDatabase
();
const
{
name
,
text
,
trainingType
=
TrainingModeEnum
.
chunk
,
chunkSize
=
512
,
chunkSplitter
,
qaPrompt
,
...
body
}
=
req
.
body
as
TextCreateDatasetCollectionParams
;
const
{
teamId
,
tmbId
,
dataset
}
=
await
authDataset
({
req
,
authToken
:
true
,
authApiKey
:
true
,
datasetId
:
body
.
datasetId
,
per
:
'w'
});
// 1. split text to chunks
const
{
chunks
}
=
splitText2Chunks
({
text
,
chunkLen
:
chunkSize
,
overlapRatio
:
trainingType
===
TrainingModeEnum
.
chunk
?
0.2
:
0
,
customReg
:
chunkSplitter
?
[
chunkSplitter
]
:
[]
});
// 2. check dataset limit
await
checkDatasetLimit
({
teamId
,
freeSize
:
global
.
feConfigs
?.
subscription
?.
datasetStoreFreeSize
,
insertLen
:
predictDataLimitLength
(
trainingType
,
chunks
)
});
// 3. create collection and training bill
const
[
collectionId
,
{
billId
}]
=
await
Promise
.
all
([
createOneCollection
({
...
body
,
teamId
,
tmbId
,
type
:
DatasetCollectionTypeEnum
.
virtual
,
name
,
trainingType
,
chunkSize
,
chunkSplitter
,
qaPrompt
,
hashRawText
:
hashStr
(
text
),
rawTextLength
:
text
.
length
}),
createTrainingBill
({
teamId
,
tmbId
,
appName
:
name
,
billSource
:
BillSourceEnum
.
training
,
vectorModel
:
getVectorModel
(
dataset
.
vectorModel
)?.
name
,
agentModel
:
getQAModel
(
dataset
.
agentModel
)?.
name
})
]);
// 4. push chunks to training queue
const
insertResults
=
await
pushDataToTrainingQueue
({
teamId
,
tmbId
,
collectionId
,
trainingMode
:
trainingType
,
prompt
:
qaPrompt
,
billId
,
data
:
chunks
.
map
((
text
,
index
)
=>
({
q
:
text
,
chunkIndex
:
index
}))
});
jsonRes
(
res
,
{
data
:
{
collectionId
,
results
:
insertResults
}
});
}
catch
(
err
)
{
jsonRes
(
res
,
{
code
:
500
,
error
:
err
});
}
}
export
const
config
=
{
api
:
{
bodyParser
:
{
sizeLimit
:
'10mb'
}
}
};
projects/app/src/pages/api/core/dataset/create.ts
View file @
aab6ee51
...
...
@@ -6,6 +6,7 @@ import type { CreateDatasetParams } from '@/global/core/dataset/api.d';
import
{
createDefaultCollection
}
from
'@fastgpt/service/core/dataset/collection/controller'
;
import
{
authUserNotVisitor
}
from
'@fastgpt/service/support/permission/auth/user'
;
import
{
DatasetTypeEnum
}
from
'@fastgpt/global/core/dataset/constants'
;
import
{
getQAModel
,
getVectorModel
}
from
'@/service/core/ai/model'
;
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
<
any
>
)
{
try
{
...
...
@@ -13,18 +14,18 @@ export default async function handler(req: NextApiRequest, res: NextApiResponse<
const
{
parentId
,
name
,
type
,
type
=
DatasetTypeEnum
.
dataset
,
avatar
,
vectorModel
=
global
.
vectorModels
[
0
].
model
,
agentModel
=
global
.
qaModels
[
0
].
model
}
=
req
.
body
as
CreateDatasetParams
;
// auth
const
{
teamId
,
tmbId
}
=
await
authUserNotVisitor
({
req
,
authToken
:
true
});
const
{
teamId
,
tmbId
}
=
await
authUserNotVisitor
({
req
,
authToken
:
true
,
authApiKey
:
true
});
// check model valid
const
vectorModelStore
=
g
lobal
.
vectorModels
.
find
((
item
)
=>
item
.
model
===
vectorModel
);
const
agentModelStore
=
g
lobal
.
qaModels
.
find
((
item
)
=>
item
.
model
===
agentModel
);
const
vectorModelStore
=
g
etVectorModel
(
vectorModel
);
const
agentModelStore
=
g
etQAModel
(
agentModel
);
if
(
!
vectorModelStore
||
!
agentModelStore
)
{
throw
new
Error
(
'vectorModel or qaModel is invalid'
);
}
...
...
projects/app/src/pages/api/core/dataset/delete.ts
View file @
aab6ee51
...
...
@@ -18,7 +18,13 @@ export default async function handler(req: NextApiRequest, res: NextApiResponse<
}
// auth owner
const
{
teamId
}
=
await
authDataset
({
req
,
authToken
:
true
,
datasetId
,
per
:
'owner'
});
const
{
teamId
}
=
await
authDataset
({
req
,
authToken
:
true
,
authApiKey
:
true
,
datasetId
,
per
:
'owner'
});
const
datasets
=
await
findDatasetAndAllChildren
({
teamId
,
...
...
projects/app/src/pages/api/plusApi/[...path].ts
deleted
100644 → 0
View file @
91b7d81c
import
type
{
NextApiRequest
,
NextApiResponse
}
from
'next'
;
import
{
jsonRes
}
from
'@fastgpt/service/common/response'
;
import
{
request
}
from
'@fastgpt/service/common/api/plusRequest'
;
import
type
{
Method
}
from
'axios'
;
import
{
setCookie
}
from
'@fastgpt/service/support/permission/controller'
;
import
{
connectToDatabase
}
from
'@/service/mongo'
;
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
)
{
try
{
await
connectToDatabase
();
const
method
=
(
req
.
method
||
'POST'
)
as
Method
;
const
{
path
=
[],
...
query
}
=
req
.
query
as
any
;
const
url
=
`/
${
path
?.
join
(
'/'
)}?
$
{
new
URLSearchParams
(
query
).
toString
()}
`;
if (!url) {
throw new Error('url is empty');
}
const data = req.body || query;
const repose = await request(
url,
data,
{
headers: {
...req.headers,
// @ts-ignore
rootkey: undefined
}
},
method
);
/* special response */
// response cookie
if (repose?.cookie) {
setCookie(res, repose.cookie);
return jsonRes(res, {
data: repose?.cookie
});
}
jsonRes(res, {
data: repose
});
} catch (error) {
jsonRes(res, {
code: 500,
error
});
}
}
export const config = {
api: {
bodyParser: {
sizeLimit: '10mb'
},
responseLimit: '10mb'
}
};
projects/app/src/pages/api/proApi/[...path].ts
0 → 100644
View file @
aab6ee51
import
type
{
NextApiRequest
,
NextApiResponse
}
from
'next'
;
import
{
jsonRes
}
from
'@fastgpt/service/common/response'
;
import
{
connectToDatabase
}
from
'@/service/mongo'
;
import
{
request
}
from
'http'
;
import
{
FastGPTProUrl
}
from
'@fastgpt/service/common/system/constants'
;
import
url
from
'url'
;
export
default
async
function
handler
(
req
:
NextApiRequest
,
res
:
NextApiResponse
)
{
try
{
await
connectToDatabase
();
const
{
path
=
[],
...
query
}
=
req
.
query
as
any
;
const
requestPath
=
`/api/
${
path
?.
join
(
'/'
)}?
$
{
new
URLSearchParams
(
query
).
toString
()}
`;
if (!requestPath) {
throw new Error('url is empty');
}
const parsedUrl = url.parse(FastGPTProUrl);
delete req.headers?.rootkey;
const requestResult = request({
protocol: parsedUrl.protocol,
hostname: parsedUrl.hostname,
port: parsedUrl.port,
path: requestPath,
method: req.method,
headers: req.headers
});
req.pipe(requestResult);
requestResult.on('response', (response) => {
Object.keys(response.headers).forEach((key) => {
// @ts-ignore
res.setHeader(key, response.headers[key]);
});
response.statusCode && res.writeHead(response.statusCode);
response.pipe(res);
});
requestResult.on('error', (e) => {
res.send(e);
res.end();
});
} catch (error) {
jsonRes(res, {
code: 500,
error
});
}
}
export const config = {
api: {
bodyParser: false
}
};
projects/app/src/pages/dataset/detail/index.tsx
View file @
aab6ee51
...
...
@@ -87,7 +87,7 @@ const Detail = ({ datasetId, currentTab }: { datasetId: string; currentTab: `${T
onError
(
err
:
any
)
{
router
.
replace
(
`/dataset/list`
);
toast
({
title
:
getErrText
(
err
,
t
(
'common.Load Failed'
)),
title
:
t
(
getErrText
(
err
,
t
(
'common.Load Failed'
)
)),
status
:
'error'
});
}
...
...
projects/app/src/pages/dataset/list/index.tsx
View file @
aab6ee51
...
...
@@ -46,13 +46,15 @@ import { PermissionTypeEnum } from '@fastgpt/global/support/permission/constant'
import
{
DatasetItemType
}
from
'@fastgpt/global/core/dataset/type'
;
import
ParentPaths
from
'@/components/common/ParentPaths'
;
import
DatasetTypeTag
from
'@/components/core/dataset/DatasetTypeTag'
;
import
{
useToast
}
from
'@/web/common/hooks/useToast'
;
import
{
getErrText
}
from
'@fastgpt/global/common/error/utils'
;
const
CreateModal
=
dynamic
(()
=>
import
(
'./component/CreateModal'
),
{
ssr
:
false
});
const
MoveModal
=
dynamic
(()
=>
import
(
'./component/MoveModal'
),
{
ssr
:
false
});
const
Kb
=
()
=>
{
const
{
t
}
=
useTranslation
();
const
theme
=
useTheme
();
const
{
toast
}
=
useToast
();
const
router
=
useRouter
();
const
{
parentId
}
=
router
.
query
as
{
parentId
:
string
};
const
{
setLoading
}
=
useSystemStore
();
...
...
@@ -115,9 +117,20 @@ const Kb = () => {
errorToast
:
t
(
'dataset.Export Dataset Limit Error'
)
});
const
{
data
,
refetch
,
isFetching
}
=
useQuery
([
'loadDataset'
,
parentId
],
()
=>
{
return
Promise
.
all
([
loadDatasets
(
parentId
),
getDatasetPaths
(
parentId
)]);
});
const
{
data
,
refetch
,
isFetching
}
=
useQuery
(
[
'loadDataset'
,
parentId
],
()
=>
{
return
Promise
.
all
([
loadDatasets
(
parentId
),
getDatasetPaths
(
parentId
)]);
},
{
onError
(
err
)
{
toast
({
status
:
'error'
,
title
:
t
(
getErrText
(
err
))
});
}
}
);
const
paths
=
data
?.[
1
]
||
[];
...
...
projects/app/src/pages/login/provider.tsx
View file @
aab6ee51
...
...
@@ -106,9 +106,9 @@ const provider = ({ code, state, error }: { code: string; state: string; error?:
export
async
function
getServerSideProps
(
content
:
any
)
{
return
{
props
:
{
code
:
content
?.
query
?.
code
,
state
:
content
?.
query
?.
state
,
error
:
content
?.
query
?.
error
,
code
:
content
?.
query
?.
code
||
''
,
state
:
content
?.
query
?.
state
||
''
,
error
:
content
?.
query
?.
error
||
''
,
...(
await
serviceSideProps
(
content
))
}
};
...
...
projects/app/src/web/common/hooks/useConfirm.tsx
View file @
aab6ee51
import
{
useCallback
,
useEffect
,
useMemo
,
useRef
,
useState
}
from
'react'
;
import
React
,
{
useCallback
,
useEffect
,
useMemo
,
useRef
,
useState
}
from
'react'
;
import
{
useDisclosure
,
Button
,
ModalBody
,
ModalFooter
}
from
'@chakra-ui/react'
;
import
{
useTranslation
}
from
'next-i18next'
;
import
MyModal
from
'@/components/MyModal'
;
...
...
@@ -35,7 +35,7 @@ export const useConfirm = (props?: {
content
,
showCancel
=
true
}
=
props
||
{};
const
[
customContent
,
setCustomContent
]
=
useState
(
content
);
const
[
customContent
,
setCustomContent
]
=
useState
<
string
|
React
.
ReactNode
>
(
content
);
const
{
isOpen
,
onOpen
,
onClose
}
=
useDisclosure
();
...
...
@@ -44,7 +44,7 @@ export const useConfirm = (props?: {
return
{
openConfirm
:
useCallback
(
(
confirm
?:
any
,
cancel
?:
any
,
customContent
?:
string
)
=>
{
(
confirm
?:
any
,
cancel
?:
any
,
customContent
?:
string
|
React
.
ReactNode
)
=>
{
confirmCb
.
current
=
confirm
;
cancelCb
.
current
=
cancel
;
...
...
projects/app/src/web/core/dataset/api.ts
View file @
aab6ee51
...
...
@@ -58,7 +58,7 @@ export const putDatasetById = (data: DatasetUpdateBody) => PUT<void>(`/core/data
export
const
delDatasetById
=
(
id
:
string
)
=>
DELETE
(
`/core/dataset/delete?id=
${
id
}
`
);
export
const
postWebsiteSync
=
(
data
:
PostWebsiteSyncParams
)
=>
POST
(
`/p
lus
Api/core/dataset/websiteSync`
,
data
,
{
POST
(
`/p
ro
Api/core/dataset/websiteSync`
,
data
,
{
timeout
:
600000
}).
catch
();
...
...
@@ -76,7 +76,7 @@ export const getDatasetCollectionById = (id: string) =>
export
const
postDatasetCollection
=
(
data
:
CreateDatasetCollectionParams
)
=>
POST
<
string
>
(
`/core/dataset/collection/create`
,
data
);
export
const
postCreateDatasetLinkCollection
=
(
data
:
LinkCreateDatasetCollectionParams
)
=>
POST
<
{
collectionId
:
string
}
>
(
`/core/dataset/collection/create/link`
,
data
);
POST
<
{
collectionId
:
string
}
>
(
`/
proApi/
core/dataset/collection/create/link`
,
data
);
export
const
putDatasetCollectionById
=
(
data
:
UpdateDatasetCollectionParams
)
=>
POST
(
`/core/dataset/collection/update`
,
data
);
...
...
projects/app/src/web/core/dataset/utils.ts
View file @
aab6ee51
...
...
@@ -27,18 +27,22 @@ export const fileCollectionCreate = ({
form
.
append
(
'bucketName'
,
BucketNameEnum
.
dataset
);
form
.
append
(
'file'
,
file
,
encodeURIComponent
(
file
.
name
));
return
POST
<
string
>
(
`/core/dataset/collection/create/file?datasetId=
${
data
.
datasetId
}
`
,
form
,
{
timeout
:
480000
,
onUploadProgress
:
(
e
)
=>
{
if
(
!
e
.
total
)
return
;
return
POST
<
string
>
(
`/proApi/core/dataset/collection/create/emptyFile?datasetId=
${
data
.
datasetId
}
`
,
form
,
{
timeout
:
480000
,
onUploadProgress
:
(
e
)
=>
{
if
(
!
e
.
total
)
return
;
const
percent
=
Math
.
round
((
e
.
loaded
/
e
.
total
)
*
100
);
percentListen
&&
percentListen
(
percent
);
},
headers
:
{
'Content-Type'
:
'multipart/form-data; charset=utf-8'
const
percent
=
Math
.
round
((
e
.
loaded
/
e
.
total
)
*
100
);
percentListen
&&
percentListen
(
percent
);
},
headers
:
{
'Content-Type'
:
'multipart/form-data; charset=utf-8'
}
}
}
);
);
};
export
async
function
chunksUpload
({
...
...
projects/app/src/web/support/activity/promotion/api.ts
View file @
aab6ee51
...
...
@@ -7,8 +7,8 @@ export const getPromotionInitData = () =>
GET
<
{
invitedAmount
:
number
;
earningsAmount
:
number
;
}
>
(
'/p
lus
Api/support/activity/promotion/getPromotionData'
);
}
>
(
'/p
ro
Api/support/activity/promotion/getPromotionData'
);
/* promotion records */
export
const
getPromotionRecords
=
(
data
:
RequestPaging
)
=>
POST
<
PromotionRecordType
>
(
`/p
lus
Api/support/activity/promotion/getPromotions`
,
data
);
POST
<
PromotionRecordType
>
(
`/p
ro
Api/support/activity/promotion/getPromotions`
,
data
);
projects/app/src/web/support/user/api.ts
View file @
aab6ee51
...
...
@@ -14,14 +14,14 @@ export const sendAuthCode = (data: {
username
:
string
;
type
:
`
${
UserAuthTypeEnum
}
`
;
googleToken
:
string
;
})
=>
POST
(
`/p
lus
Api/support/user/inform/sendAuthCode`
,
data
);
})
=>
POST
(
`/p
ro
Api/support/user/inform/sendAuthCode`
,
data
);
export
const
getTokenLogin
=
()
=>
GET
<
UserType
>
(
'/support/user/account/tokenLogin'
,
{},
{
maxQuantity
:
1
});
export
const
oauthLogin
=
(
params
:
OauthLoginProps
)
=>
POST
<
ResLogin
>
(
'/p
lus
Api/support/user/account/login/oauth'
,
params
);
POST
<
ResLogin
>
(
'/p
ro
Api/support/user/account/login/oauth'
,
params
);
export
const
postFastLogin
=
(
params
:
FastLoginProps
)
=>
POST
<
ResLogin
>
(
'/p
lus
Api/support/user/account/login/fastLogin'
,
params
);
POST
<
ResLogin
>
(
'/p
ro
Api/support/user/account/login/fastLogin'
,
params
);
export
const
postRegister
=
({
username
,
...
...
@@ -34,7 +34,7 @@ export const postRegister = ({
password
:
string
;
inviterId
?:
string
;
})
=>
POST
<
ResLogin
>
(
`/p
lus
Api/support/user/account/register/emailAndPhone`
,
{
POST
<
ResLogin
>
(
`/p
ro
Api/support/user/account/register/emailAndPhone`
,
{
username
,
code
,
inviterId
,
...
...
@@ -50,7 +50,7 @@ export const postFindPassword = ({
code
:
string
;
password
:
string
;
})
=>
POST
<
ResLogin
>
(
`/p
lus
Api/support/user/account/password/updateByCode`
,
{
POST
<
ResLogin
>
(
`/p
ro
Api/support/user/account/password/updateByCode`
,
{
username
,
code
,
password
:
hashStr
(
password
)
...
...
projects/app/src/web/support/user/inform/api.ts
View file @
aab6ee51
...
...
@@ -3,7 +3,7 @@ import type { PagingData, RequestPaging } from '@/types';
import
type
{
UserInformSchema
}
from
'@fastgpt/global/support/user/inform/type'
;
export
const
getInforms
=
(
data
:
RequestPaging
)
=>
POST
<
PagingData
<
UserInformSchema
>>
(
`/p
lus
Api/support/user/inform/list`
,
data
);
POST
<
PagingData
<
UserInformSchema
>>
(
`/p
ro
Api/support/user/inform/list`
,
data
);
export
const
getUnreadCount
=
()
=>
GET
<
number
>
(
`/p
lus
Api/support/user/inform/countUnread`
);
export
const
readInform
=
(
id
:
string
)
=>
GET
(
`/p
lus
Api/support/user/inform/read`
,
{
id
});
export
const
getUnreadCount
=
()
=>
GET
<
number
>
(
`/p
ro
Api/support/user/inform/countUnread`
);
export
const
readInform
=
(
id
:
string
)
=>
GET
(
`/p
ro
Api/support/user/inform/read`
,
{
id
});
projects/app/src/web/support/user/team/api.ts
View file @
aab6ee51
...
...
@@ -16,29 +16,29 @@ import {
/* --------------- team ---------------- */
export
const
getTeamList
=
(
status
:
`
${
TeamMemberSchema
[
'status'
]}
`
)
=>
GET
<
TeamItemType
[]
>
(
`/p
lus
Api/support/user/team/list`
,
{
status
});
GET
<
TeamItemType
[]
>
(
`/p
ro
Api/support/user/team/list`
,
{
status
});
export
const
postCreateTeam
=
(
data
:
CreateTeamProps
)
=>
POST
<
string
>
(
`/p
lus
Api/support/user/team/create`
,
data
);
POST
<
string
>
(
`/p
ro
Api/support/user/team/create`
,
data
);
export
const
putUpdateTeam
=
(
data
:
UpdateTeamProps
)
=>
PUT
(
`/p
lus
Api/support/user/team/update`
,
data
);
PUT
(
`/p
ro
Api/support/user/team/update`
,
data
);
export
const
putSwitchTeam
=
(
teamId
:
string
)
=>
PUT
<
string
>
(
`/p
lus
Api/support/user/team/switch`
,
{
teamId
});
PUT
<
string
>
(
`/p
ro
Api/support/user/team/switch`
,
{
teamId
});
/* --------------- team member ---------------- */
export
const
getTeamMembers
=
(
teamId
:
string
)
=>
GET
<
TeamMemberItemType
[]
>
(
`/p
lus
Api/support/user/team/member/list`
,
{
teamId
});
GET
<
TeamMemberItemType
[]
>
(
`/p
ro
Api/support/user/team/member/list`
,
{
teamId
});
export
const
postInviteTeamMember
=
(
data
:
InviteMemberProps
)
=>
POST
<
InviteMemberResponse
>
(
`/p
lus
Api/support/user/team/member/invite`
,
data
);
POST
<
InviteMemberResponse
>
(
`/p
ro
Api/support/user/team/member/invite`
,
data
);
export
const
putUpdateMember
=
(
data
:
UpdateTeamMemberProps
)
=>
PUT
(
`/p
lus
Api/support/user/team/member/update`
,
data
);
PUT
(
`/p
ro
Api/support/user/team/member/update`
,
data
);
export
const
putUpdateMemberName
=
(
name
:
string
)
=>
PUT
(
`/p
lus
Api/support/user/team/member/updateName`
,
{
name
});
PUT
(
`/p
ro
Api/support/user/team/member/updateName`
,
{
name
});
export
const
delRemoveMember
=
(
props
:
DelMemberProps
)
=>
DELETE
(
`/p
lus
Api/support/user/team/member/delete`
,
props
);
DELETE
(
`/p
ro
Api/support/user/team/member/delete`
,
props
);
export
const
updateInviteResult
=
(
data
:
UpdateInviteProps
)
=>
PUT
(
'/p
lus
Api/support/user/team/member/updateInvite'
,
data
);
PUT
(
'/p
ro
Api/support/user/team/member/updateInvite'
,
data
);
export
const
delLeaveTeam
=
(
teamId
:
string
)
=>
DELETE
(
'/p
lus
Api/support/user/team/member/leave'
,
{
teamId
});
DELETE
(
'/p
ro
Api/support/user/team/member/leave'
,
{
teamId
});
/* team limit */
export
const
checkTeamExportDatasetLimit
=
(
datasetId
:
string
)
=>
...
...
projects/app/src/web/support/wallet/bill/api.ts
View file @
aab6ee51
...
...
@@ -4,7 +4,7 @@ import type { PagingData, RequestPaging } from '@/types';
import
type
{
BillItemType
}
from
'@fastgpt/global/support/wallet/bill/type'
;
export
const
getUserBills
=
(
data
:
RequestPaging
)
=>
POST
<
PagingData
<
BillItemType
>>
(
`/p
lus
Api/support/wallet/bill/getBill`
,
data
);
POST
<
PagingData
<
BillItemType
>>
(
`/p
ro
Api/support/wallet/bill/getBill`
,
data
);
export
const
postCreateTrainingBill
=
(
data
:
CreateTrainingBillProps
)
=>
POST
<
string
>
(
`/support/wallet/bill/createTrainingBill`
,
data
);
projects/app/src/web/support/wallet/pay/api.ts
View file @
aab6ee51
import
{
GET
}
from
'@/web/common/api/request'
;
import
type
{
PaySchema
}
from
'@fastgpt/global/support/wallet/pay/type.d'
;
export
const
getPayOrders
=
()
=>
GET
<
PaySchema
[]
>
(
`/p
lus
Api/support/wallet/pay/getPayOrders`
);
export
const
getPayOrders
=
()
=>
GET
<
PaySchema
[]
>
(
`/p
ro
Api/support/wallet/pay/getPayOrders`
);
export
const
getPayCode
=
(
amount
:
number
)
=>
GET
<
{
codeUrl
:
string
;
payId
:
string
;
}
>
(
`/p
lus
Api/support/wallet/pay/getPayCode`
,
{
amount
});
}
>
(
`/p
ro
Api/support/wallet/pay/getPayCode`
,
{
amount
});
export
const
checkPayResult
=
(
payId
:
string
)
=>
GET
<
string
>
(
`/p
lus
Api/support/wallet/pay/checkPayResult`
,
{
payId
}).
then
((
data
)
=>
{
GET
<
string
>
(
`/p
ro
Api/support/wallet/pay/checkPayResult`
,
{
payId
}).
then
((
data
)
=>
{
try
{
GET
(
'/common/system/unlockTask'
);
}
catch
(
error
)
{}
...
...
projects/app/src/web/support/wallet/sub/api.ts
View file @
aab6ee51
...
...
@@ -10,4 +10,4 @@ export const getTeamDatasetValidSub = () =>
}
>
(
`/support/wallet/sub/getDatasetSub`
);
export
const
postExpandTeamDatasetSub
=
(
data
:
SubDatasetSizeParams
)
=>
POST
(
'/p
lus
Api/support/wallet/sub/datasetSize/expand'
,
data
);
POST
(
'/p
ro
Api/support/wallet/sub/datasetSize/expand'
,
data
);
Write
Preview
Markdown
is supported
0%
Try again
or
attach a new file
Attach a file
Cancel
You are about to add
0
people
to the discussion. Proceed with caution.
Finish editing this message first!
Cancel
Please
register
or
sign in
to comment

